Uncategorized
What Is Jev AI? A Practical Guide to System One and Executable Decisions
Jev AI is a decision model for software: provide business state and typed questions, then receive structured results, probabilities, and confidence signals for classification, routing, scoring, and safety checks.
What Is Jev AI? A Practical Guide to System One and Executable Decisions
When you add AI to an agent, support system, workflow, or SaaS product, the hardest part is often not asking a model to write a paragraph. The hard part is making small decisions consistently across many requests: Which team should receive this ticket? Does this action need human approval? How urgent is the task? Which model or tool should run next?
Jev AI is designed to turn those judgments into structured decisions that software can consume directly. The Jev AI website positions Jev as a decision tool for software teams. TypeSafe’s official documentation describes it as its flagship model and first System One model: provide state and typed questions, then receive choices, scores, yes/no judgments, and probability signals.
This guide explains what Jev AI is, how it works, where it fits alongside generative LLMs, how to connect its API, and which limitations should shape a production design.
Short version: Jev AI is not a replacement for every conversational AI system. It is a decision layer inside your application for fast, repeatable classification, routing, scoring, and safety checks within a defined answer space.
Table of contents
- What is Jev AI
- How Jev AI works
- The three question types
- Why not ask an LLM for JSON
- Where Jev AI fits
- How to get started
- Probability, confidence, and limits
- Jev AI pricing
- Frequently asked questions
What is Jev AI
A System One model for software
Large language models are primarily designed to generate text for people to read. When software needs a narrow judgment, developers often add three extra steps: describe an output format in a prompt, parse a natural-language or JSON response, and then decide whether to execute an action. That approach is flexible, but it also brings formatting errors, extra text, and uncertainty into the application layer.
Jev AI uses a different interface:
- State: Send a ticket, message, form fields, or a JSON object as the decision context.
- Typed questions: Define the exact kind of judgment the application needs.
- Structured result: Receive a result that code can branch on, sort, route, or store.
Read the Jev AI homepage for the product positioning, and see the official TypeSafe introduction for the System One model and its primitives.
Jev AI versus generative LLMs
Jev AI and generative LLMs are not simply competing versions of the same product. They are useful for different jobs: LLMs are strong at open-ended generation, explanation, and creative work; Jev is intended for repeated, bounded decisions that software needs to act on.
| Dimension | Jev AI | Generative LLM | Rules-based code |
|---|---|---|---|
| Main output | Choices, scores, yes/no judgments, probabilities, and confidence | Text, code, or open-ended structured content | Deterministic values from explicit conditions |
| Best fit | Classification, routing, priority, risk checks, tool gating | Writing, summarization, Q&A, complex reasoning | Stable conditions that do not require semantic interpretation |
| Interface | State + typed questions | Prompt + context | If/else, rules engine, or query |
| Uncertainty | Exposed through probability and confidence signals | Usually requires custom validation | Usually no model probability |
| System role | A decision layer inside application logic | Generation or reasoning center | Deterministic execution layer |
Jev does not define your business policy for you. Your team still chooses the answer space, scoring rubric, thresholds, and human-review strategy.
How Jev AI works
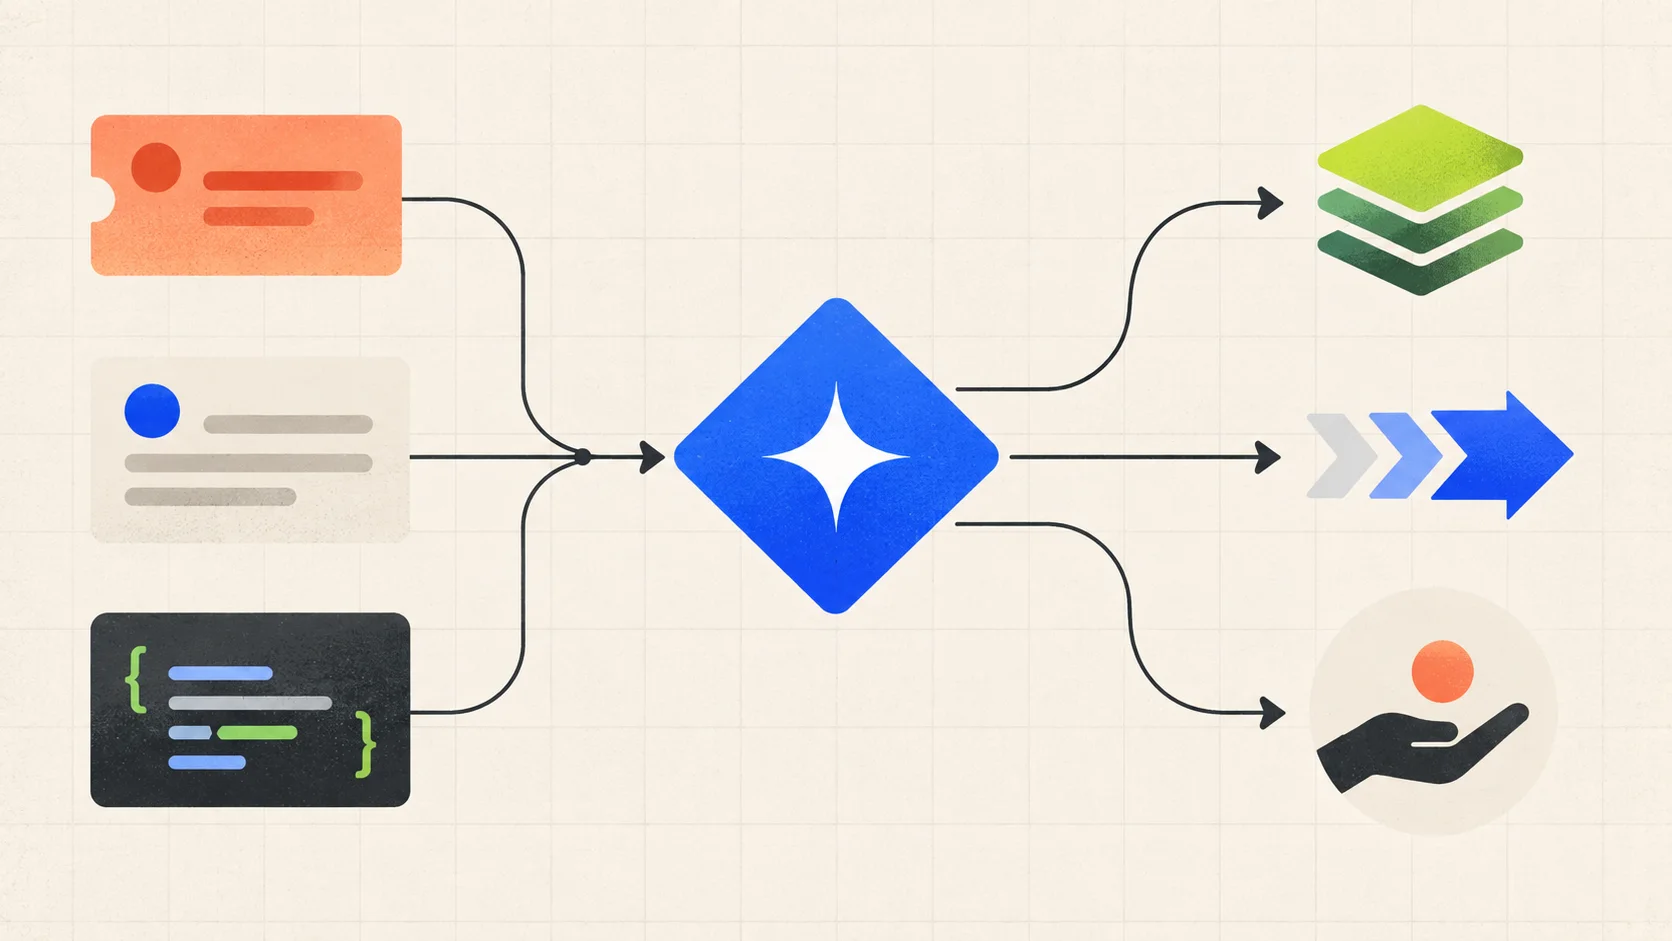
Image: Several small questions can read the same state, while application code decides what happens next.
The workflow described in the official documentation can be summarized in four steps.
1. Prepare state
State is the context that every question reads. It can be:
- a natural-language string such as a support message, alert, or user report;
- a JSON object containing a ticket, order, user tier, and policy fields;
- an array of text items such as related messages or retrieved snippets.
Questions should usually be framed around one shared state instead of placing an entire business process inside one huge prompt. The current documentation says Jev accepts text, JSON objects, and arrays of text; images, audio, and video are not currently supported as direct inputs.
2. Define typed questions
Each question should own one specific judgment. Instead of asking, “Should we retain this customer and which team should follow up?”, split it into “Which team should handle this?” and “Does this require a retention workflow?” Smaller questions are easier to test and combine in code.
3. Read the structured response
Jev returns answers using the question IDs you send. The returned fields depend on the question type: Choice can return a selected option, probabilities, and confidence; Score can return a score, legend, probabilities, and confidence; Noul returns a yes probability.
Responses can also include runtime information such as usage and elapsedMs. elapsedMs is end-to-end request time, not necessarily pure model inference time.
4. Let code decide the next action
The model makes the judgment; your application makes the move. Code can call route(), queue(), block(), request_review(), or another LLM. This keeps thresholds, permissions, audit logs, and high-risk fallbacks under application control.
To see the full flow, open the Jev AI Playground and test a real but low-risk business state.
The three question types
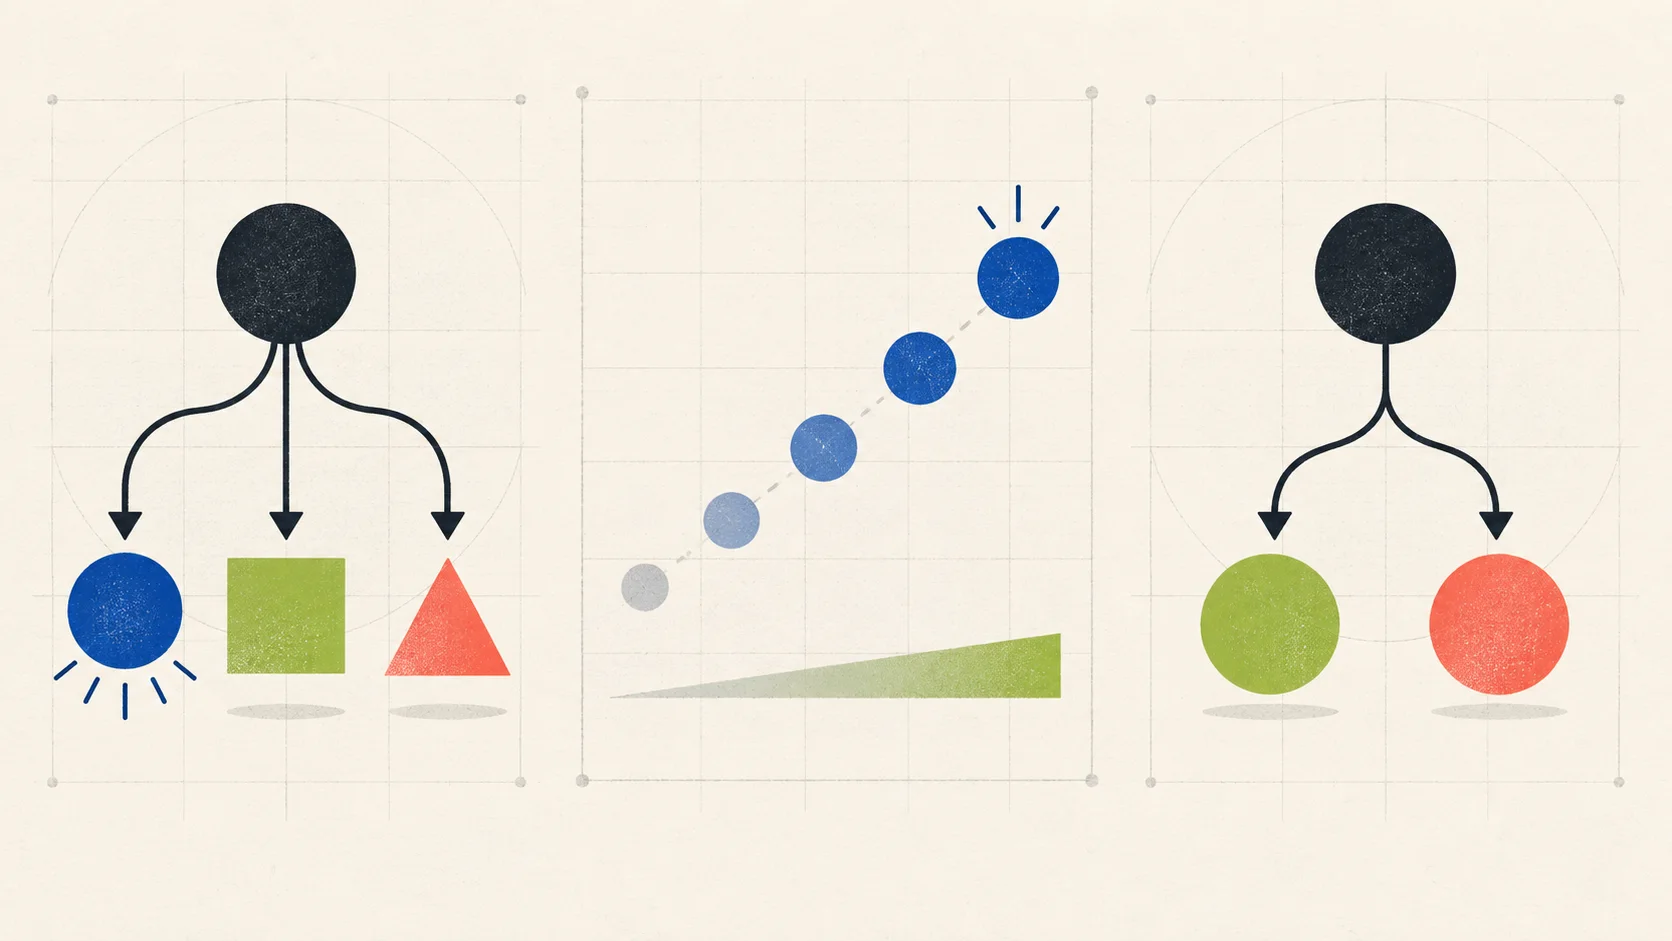
Image: The three primitives correspond to selecting, scoring, and judging whether a statement is true.
Choice: select from a defined set
Choice is designed for classification and routing. Examples include:
- Should this support request go to billing, technical support, or another team?
- Is this content a tutorial, product update, or customer story?
- Should the request use a fast model, a deeper model, or a human workflow?
Define the options and their descriptions in advance. Keep an other or none-of-the-above option when unknown cases are possible so the model is not forced to select a bad match.
Score: rate against an ordered rubric
Score fits severity, satisfaction, priority, and risk levels. You can define levels from “no action needed” to “immediate escalation” and use Jev’s probability-weighted result to rank a queue.
The rubric should be concrete. Instead of only saying “judge urgency,” describe the time requirement, customer impact, and operational consequence for each level. That makes the score more useful in SLAs and prioritization logic.
Noul: judge whether a statement is true
Noul is for binary judgments such as “Is the customer explicitly asking for a refund?” or “Should this tool call require human confirmation?” It returns a yes probability between 0 and 1, not a second confidence field.
When a conclusion contains several independent conditions, split it into multiple Noul questions and combine the results in code. This is easier to evaluate than asking one question to handle facts, risk, and action at the same time.
Read the Jev AI question documentation and the TypeSafe API documentation for current fields and examples.
Why not ask an LLM for JSON
Asking an LLM to return JSON is still a useful engineering pattern. Jev AI adds value when the decision itself has a known shape and must be repeated reliably.
The answer boundary is explicit
Choice, Score, and Noul represent different decision semantics. The developer defines the answer space first, so application code does not need to infer intent from a paragraph.
One state can support multiple questions
A support ticket can be evaluated for department, urgency, and refund intent in the same request. The official documentation says multiple questions are evaluated against the same state in parallel, which avoids chaining separate calls simply to split a decision.
Probability signals can participate in control flow
When the result is clear enough, code can route automatically. When it is close to a threshold or the action is risky, the system can request human review, ask for more information, or call a stronger model. This lets automation level change with the signal instead of treating every output as equally safe.
Policy stays in code
Jev answers a defined question about the current state. Your application still owns thresholds, permissions, retries, audit trails, and the final action. When policy changes, you can update the question definition or code without rebuilding one giant conversational prompt.
Jev is not meant for every task. Open-ended research, long explanations, and creative generation still belong with a generative model or a person.
Where Jev AI fits
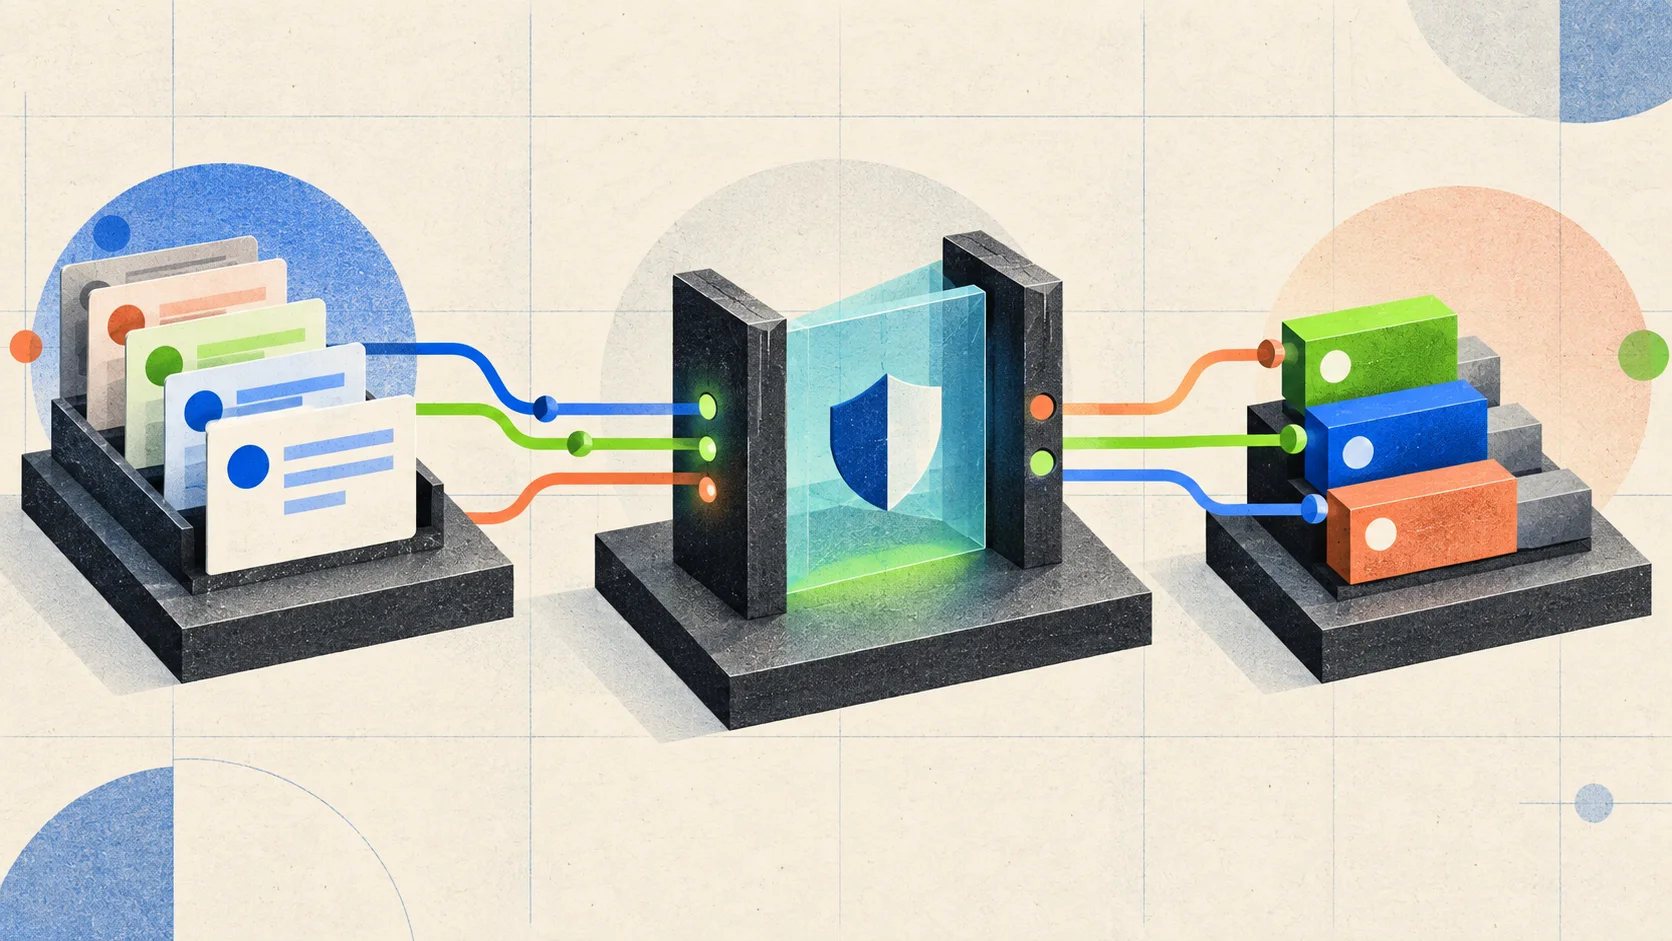
Image: Jev can act as a decision node between input, guardrails, and execution queues.
Support-ticket classification and routing
Use the ticket text, customer tier, and relevant history as state. Use Choice to select the team and Score to estimate urgency. The queue can then sort by team, score, and probability, while low-confidence cases go to human review.
Model routing for AI agents
Classify task difficulty, tool requirements, and risk before choosing a fast model, a deeper model, or a human workflow. Jev decides the path; the agent orchestration layer still manages model calls, context, and tools.
Safety checks before tool calls
Before deleting data, charging a card, changing permissions, or sending an external message, use Noul to judge whether intent is explicit and whether the request meets the required condition. High-risk actions should also use hard rules, authorization checks, and audit logs.
Queue priority and human escalation
Split impact, time requirement, and customer status into separate Score or Noul questions, then combine them into a ranking formula in code. This allows operations teams to change weights without rewriting one large prompt.
Structured information extraction
When the target fields and candidate values can be defined in advance, Jev can support lightweight classification and validation. For unknown fields, long-form extraction, or complex entity relationships, use a generative model first and Jev as a validator or router.
How to get started
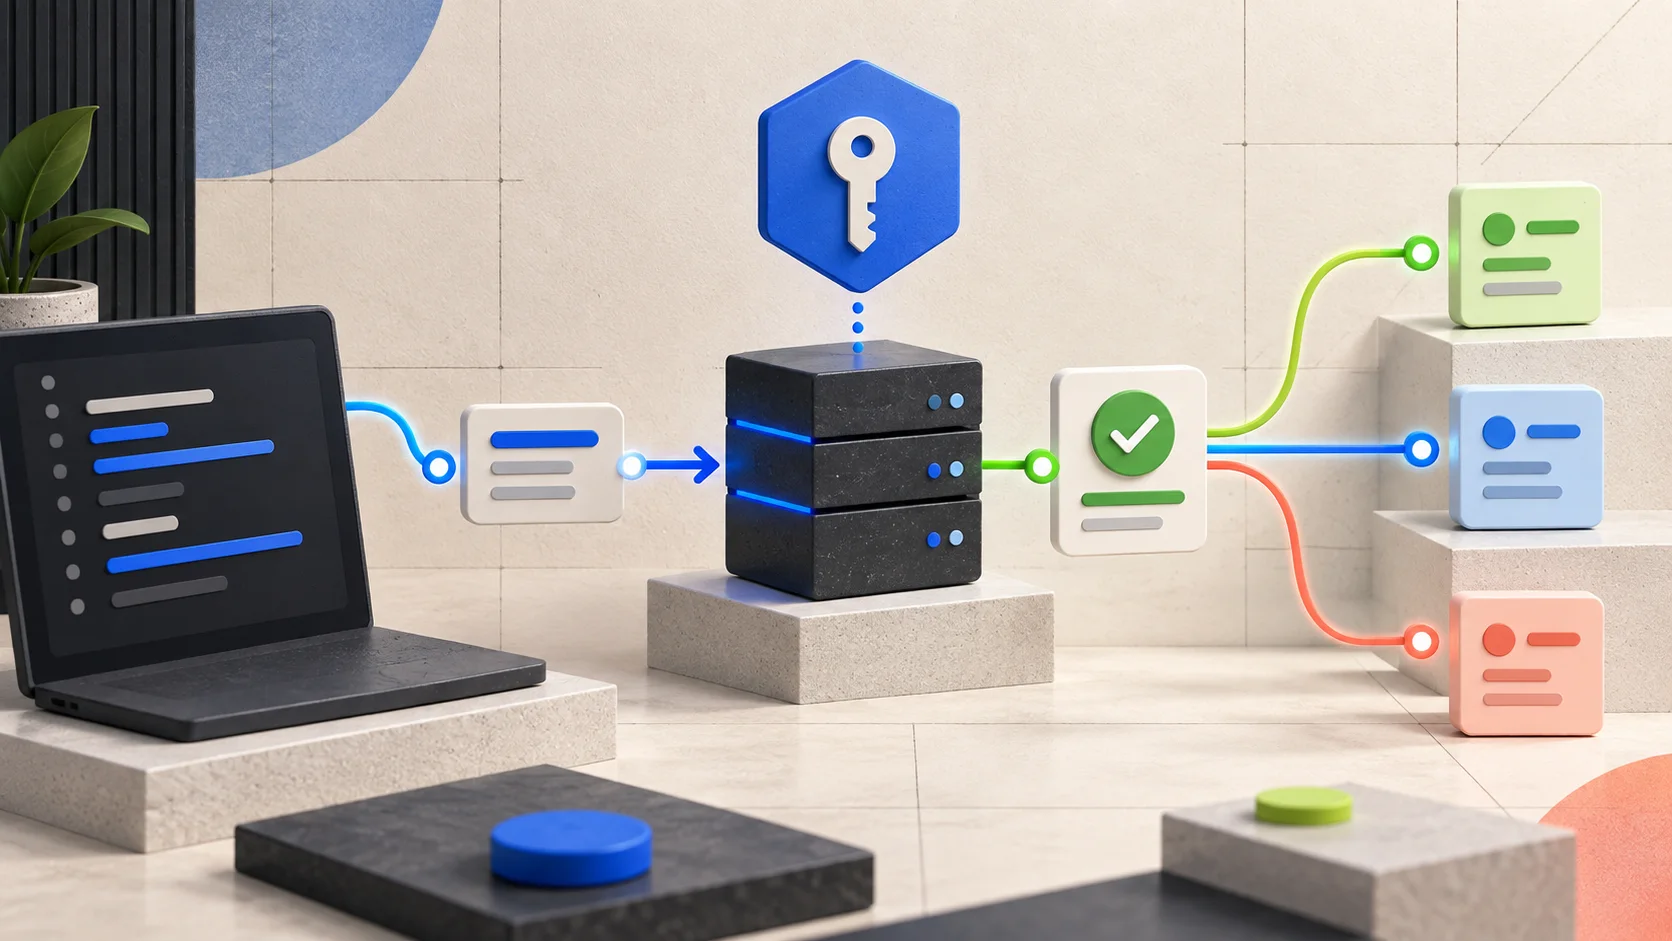
Image: Keep the API call on the server and hand the structured result back to application code.
Step 1: Validate one decision in the Playground
Choose a low-risk decision with a measurable outcome and a clear answer space. Do not move an entire workflow into the first test. Verify that one judgment actually reduces manual work or repeated application logic.
Step 2: Create an API key on the server side
After validating the workflow, follow the Jev AI API guide to create an API key. Store the key in a server-side environment variable. Never put it in browser code, a real Markdown example, or a Git repository.
Step 3: Call the systemone endpoint
The current website documentation uses POST https://thejevai.com/v1/systemone. This is a minimal Noul example based on the documented request shape:
curl -X POST https://thejevai.com/v1/systemone \
  -H "Authorization: Bearer $JEV_API_KEY" \
  -H "Content-Type: application/json" \
  -d '{
    "model": "typesafe/jev-1.13",
    "state": "A customer has tried to connect Stripe for three days.",
    "questions": {
      "urgent": {
        "type": "noul",
        "instructions": "Does this message express urgency?"
      }
    }
  }'
Conceptually, answers contains results keyed by question ID, usage contains usage information, and elapsedMs reports end-to-end request time. Production code should follow the official API reference for complete fields, validation, and error handling instead of inferring every optional parameter from a short example.
Step 4: Connect the result to control flow
A robust production flow usually includes:
- Validate length, permissions, and sensitive data before sending state.
- Send a small, well-scoped set of questions.
- Validate the response shape and request status.
- Use probability, confidence, business risk, and thresholds to choose automation or review.
- Record the input version, question definition, model version, and final action for replay and evaluation.
For current quotas, API key management, and plan details, see the Jev AI pricing page.
Probability, confidence, and limits
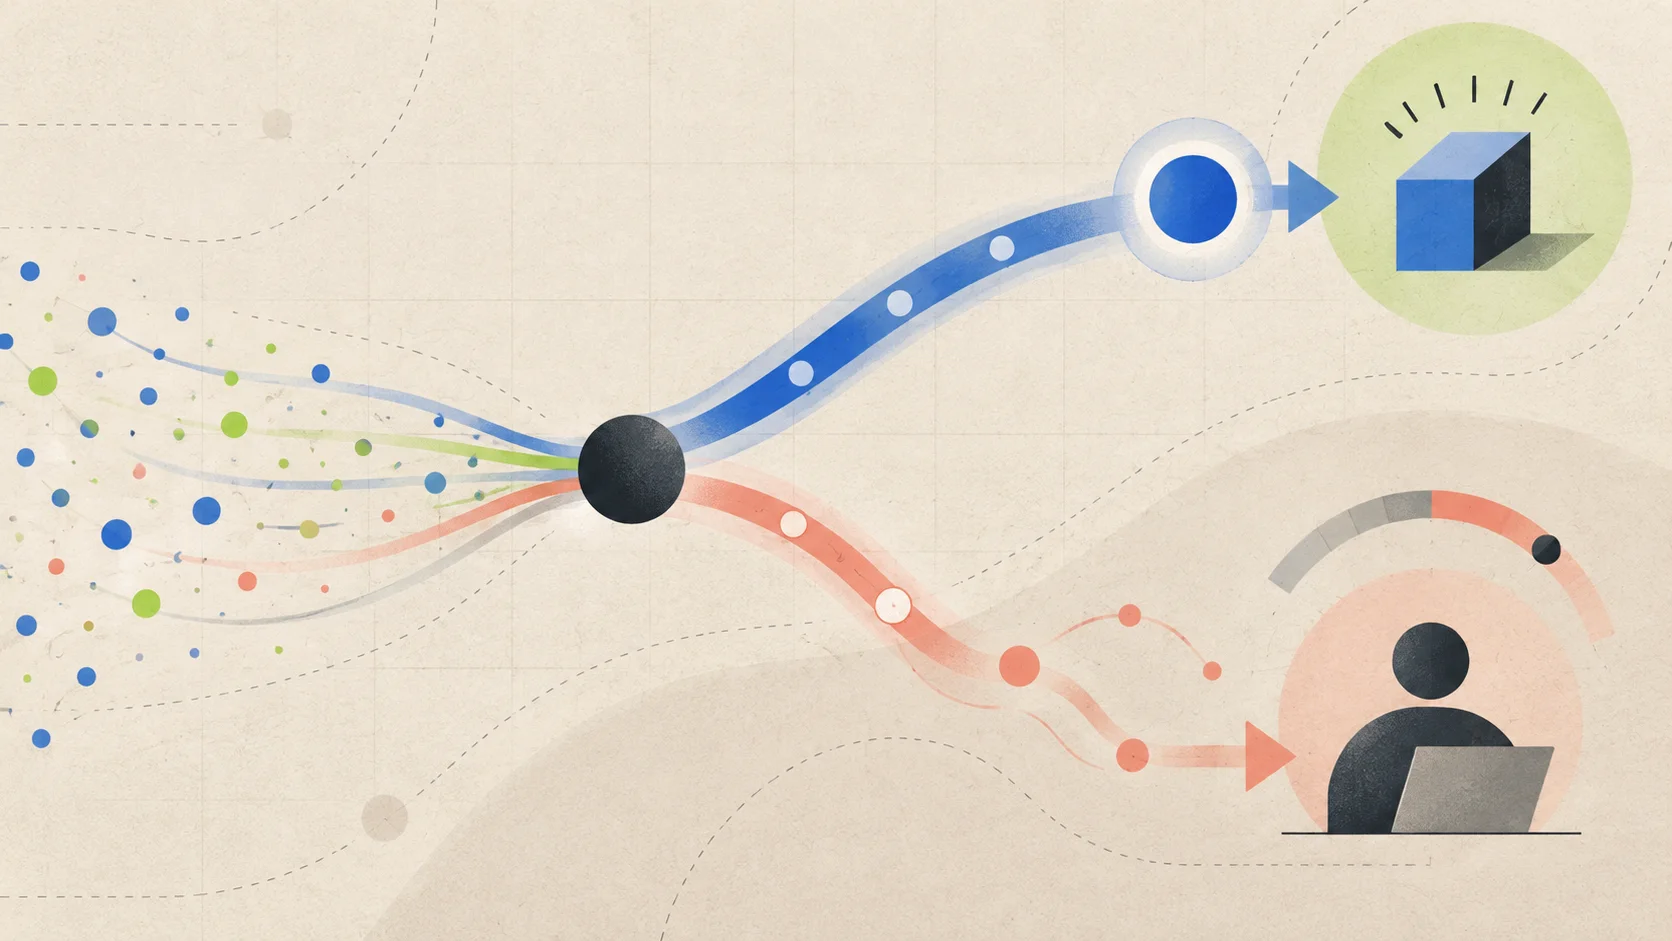
Image: Probability should help a system choose its level of automation, not replace risk controls.
Probability is not a business-accuracy guarantee
The official documentation explicitly says that probability and confidence are signals for automation, not guarantees of business accuracy. A high-confidence result can still be wrong for your domain, language, data distribution, or policy.
Use different strategies for different actions:
- Low-risk classification can use a lower threshold with a correction path.
- Medium-risk actions should include retries, counterexamples, and human sampling.
- Deletion, payment, and permission changes should combine model signals with hard rules, authorization, and human confirmation.
Keep questions narrow
A good question asks for one judgment and gives every answer a clear meaning. If a question requires long-context reasoning, several independent factors, a policy interpretation, and an action recommendation, split it into smaller questions and combine them in code.
Preprocess non-text inputs
The current site documentation lists text, JSON objects, and arrays of text as supported state inputs. Images, audio, and video are not direct inputs at this point. For Chinese, specialist terminology, or domain-specific data, build your own evaluation set and test Choice, Score, and Noul separately.
Validate latency in your environment
The Jev AI homepage presents a 70–500ms response range, but actual latency depends on network location, request size, concurrency, queues, and service conditions. Treat the number as product positioning, not as your SLA. Benchmark with real requests and your target concurrency before relying on it in production.
Jev AI pricing
The following summary reflects the pricing page displayed on September 20, 2026. Plans and benefits can change, so confirm them on the official pricing page before purchasing.
| Plan | Price | Credits and intended use |
|---|---|---|
| Starter | $10 | 100,000 credits with no expiry, for validating one real workflow |
| Pro | $100 | 1,000,000 credits, multiple workspaces, and production API usage |
| Enterprise | $1,000 | 11,000,000 credits, including 10% extra credits, team collaboration, and custom integration support |
Do not compare only the credit totals. Estimate the size of each state, the number of questions per request, whether decisions are evaluated in parallel, and how many low-confidence results will require human review.
Frequently asked questions
Is Jev AI a chatbot?
No. Jev AI is designed for software to consume structured decisions rather than for generating a conversational reply. It can sit inside a chatbot, agent, or SaaS workflow as a judgment node.
Can I use Jev AI without development experience?
You can start with the Playground to understand state, question types, and results. Connecting decisions to a product, managing API keys, permissions, retries, and human review still requires basic backend engineering.
Can Jev AI replace a large language model?
Usually not by itself. Jev is suited to bounded decisions; a generative LLM is suited to open-ended text, explanations, and deeper reasoning. In a practical system, Jev can route requests and check risky actions while an LLM handles generation or complex reasoning.
How do I choose between Choice, Score, and Noul?
- Use Choice when you need one option from a set.
- Use Score when you need an ordered assessment of severity, priority, or quality.
- Use Noul when you need to judge whether one statement is true.
Is confidence the same as accuracy?
No. Confidence and probability are signals that help an application choose its level of automation. Evaluate the model on your own data, language, domain, and risk level, and keep a human-review path for high-impact actions.
Where can I find the latest docs and examples?
Start with the official documentation, then browse the Showcase for community workflows. If you are building a specific integration, validate a small example in the Playground first.
Conclusion: make one small decision reliable first
Jev AI is not about putting every AI capability into one model. Its value is making the small judgments already hidden in software explicit: define state, ask typed questions, read probability signals, and let code decide whether to route, queue, block, or request human confirmation.
For teams building AI agents, support automation, developer tools, and business workflows, a practical starting point is one low-risk, measurable decision. Validate it in the Jev AI Playground, then connect it server-side using the API documentation. Design the boundaries, thresholds, and failure paths alongside the model call, and Jev can become a maintainable software component rather than a one-off demo.
Research date: 2026-09-20
Primary sources: thejevai.com, Jev AI documentation, Jev AI pricing, TypeSafe introduction