Developer Guides
Jev AI TypeSafe AI: A Practical Guide to Typed Decisions in Production
Understand Jev AI, TypeSafe AI, and typed decisions: design state and questions, validate responses, route actions, and ship safer AI workflows.
Jev AI TypeSafe AI: A Practical Guide to Typed Decisions in Production
If you searched for jev ai typesafe ai, you are probably trying to connect three ideas: Jev AI, TypeSafe AI, and the growing need for AI results that software can consume safely. The important distinction is that a typed decision is not simply a chat answer wrapped in JSON. It is a bounded judgment with an answer space, a response shape, and a clear place in your application’s control flow.
Jev is positioned as a decision tool for software teams. You send it a piece of state and one or more typed questions, then receive structured answers such as a selected option, a score, or a yes probability. The official Jev AI homepage describes the product around classification, routing, scoring, and safety checks rather than open-ended text generation. The public site also notes that Jev AI is independently operated and is not affiliated with, operated by, or endorsed by TypeSafe. That disclaimer matters: use “TypeSafe AI” as a search and ecosystem term, but do not assume that every TypeScript type or third-party TypeSafe project is the Jev product.
This guide explains how to think about Jev AI TypeSafe AI as a production pattern. You will learn how to design the decision contract, choose among Choice, Score, and Noul questions, validate a remote response at runtime, combine Jev with a generative LLM, and create safe fallbacks when the signal is uncertain or unavailable.
Table of contents
- What does Jev AI TypeSafe AI mean
- Why typed decisions are different from generated JSON
- The decision contract: state, questions, and policy
- The three Jev question types
- TypeScript types are not runtime validation
- A production architecture for Jev AI
- High-value use cases
- How to use probability and confidence
- Security, privacy, and operational boundaries
- A rollout plan and checklist
- When Jev is not the right tool
- Frequently asked questions
What does Jev AI TypeSafe AI mean?
The phrase usually signals a search for a typed AI interface rather than a general chatbot. In a traditional LLM integration, an application sends a prompt and receives text. The application may then ask for JSON, parse it, and hope the model followed the requested schema. That can work for low-risk enrichment, but it leaves several responsibilities mixed together: deciding what the question is, describing the answer space, extracting the answer, and deciding whether the answer is safe to act on.
Jev separates those responsibilities. Your code supplies the state and defines the questions. Jev evaluates the state against those questions and returns an answer for each question ID. Your application then applies deterministic rules, authorization, thresholds, and human-review policy.
This is the useful meaning of “typed” here:
- The question has a declared shape. It is a Choice, Score, or Noul decision rather than an unbounded request for prose.
- The answer has a corresponding shape. A Choice answer includes the selected option, probabilities, and confidence. A Score answer includes a probability-weighted score, a legend, probabilities, and confidence. A Noul answer includes a yes probability.
- The result has an application role. It can be used to route a queue, select a model, request confirmation, or send a case to review.
Typed does not mean infallible. It means the boundary between the model and your code is explicit enough to validate, evaluate, and monitor.
Why typed decisions are different from generated JSON
Generated JSON and typed decisions can look similar in a log, but their engineering contracts are different. Consider a ticket-routing task. A generative model might return:
{
  "team": "technical",
  "reason": "The customer mentions a failed integration"
}
That object is useful, but it does not tell you whether technical was one of the allowed teams, how close the alternative billing was, or whether the result was ambiguous. You need to add a schema, a parser, and a policy layer yourself.
A typed decision starts with the allowed answer space. For example, a Choice question might define billing, technical, sales, and needs_review, each with a precise criterion. The result can preserve the distribution across those options. The application can then say: route automatically only when the selected option is allowed and the confidence clears the threshold; otherwise, send the ticket to a person.
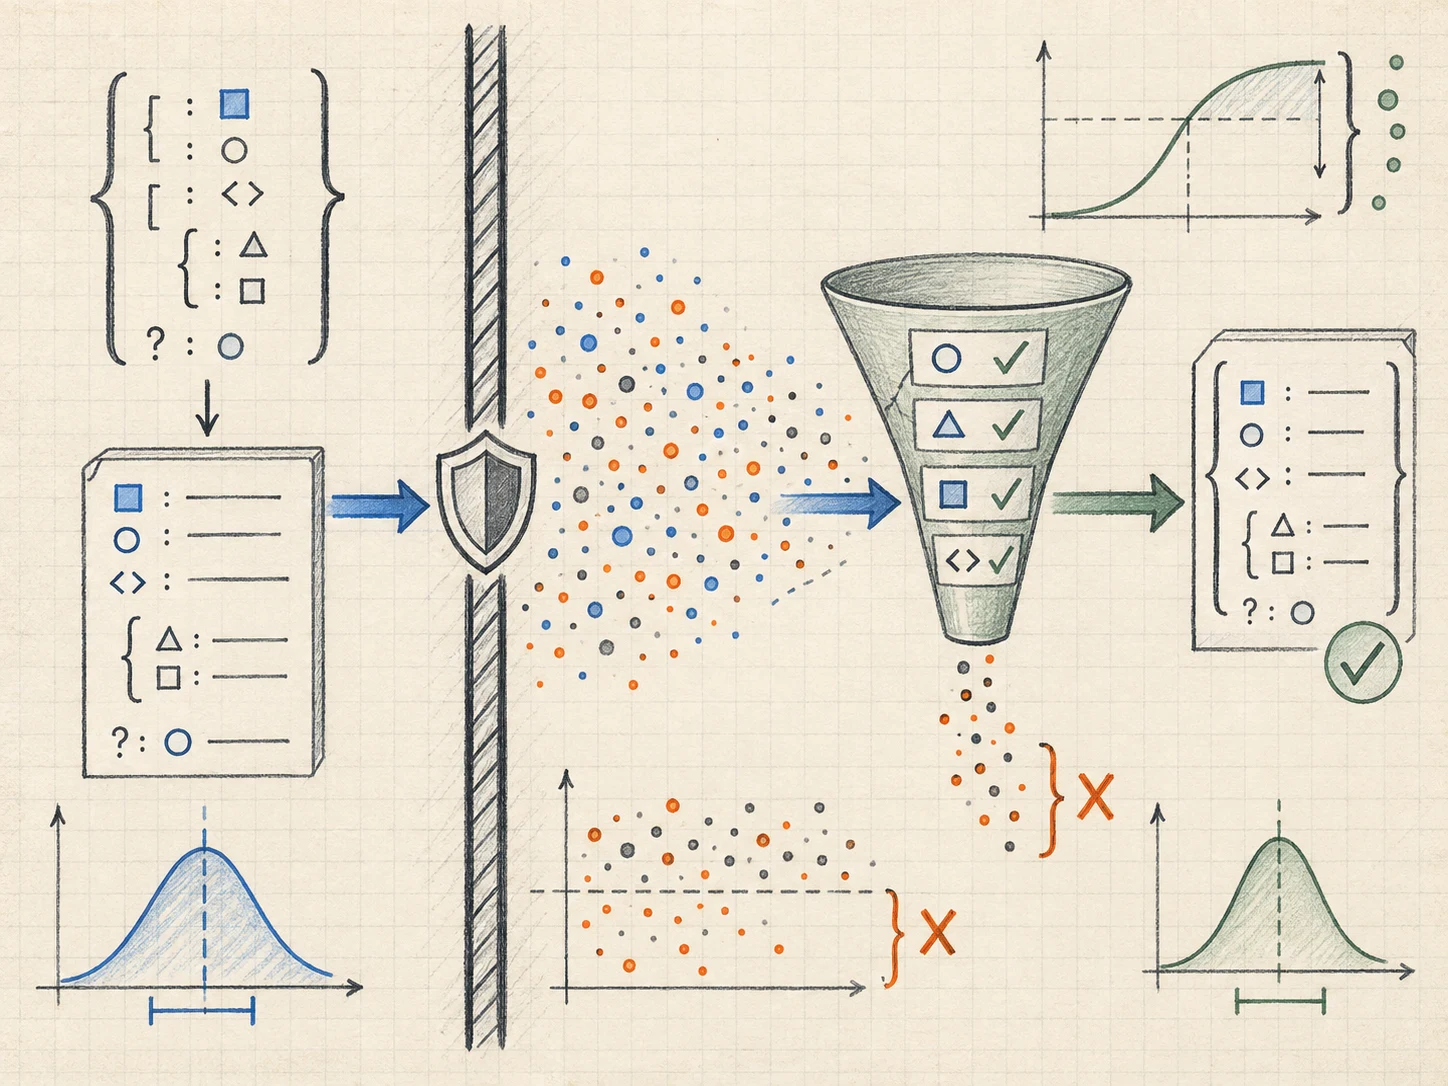
There is also a performance and workflow advantage. Multiple questions can be evaluated against one shared state. Instead of making one request to classify intent, another to score urgency, and a third to check whether human review is needed, you can describe the three independent decisions together. That keeps the decision surface visible and reduces unnecessary orchestration.
The key design principle is simple: use a model for bounded judgment, and keep the final action in ordinary application code.
The decision contract: state, questions, and policy
Before writing an API request, write a small decision contract. It should answer four questions:
- What state does the model need?
- What exact question should be answered?
- What are the valid outcomes?
- What does the application do when the result is uncertain, invalid, or unavailable?
1. Prepare only the relevant state
Jev’s documented input boundary accepts text, JSON objects, and arrays of text. A simple support message can be a string. A workflow with a ticket, account tier, product area, and policy excerpt is better represented as a JSON object. Include the information required by the question, not the entire database record.
Smaller state is easier to review and less likely to leak unrelated personal or confidential data. It also makes your evaluation set more stable: when the model sees only the fields that matter, you can understand why a decision changed.
2. Ask one decision per question ID
Use a stable key for each question, such as department, urgency, or needs_human. Avoid compound questions like “Which team should handle this, how urgent is it, and should we refund the customer?” Those are three different decisions with different answer shapes and different business owners.
The question ID is part of your application contract. A label shown in an admin panel can change; the key used by code should change only through a deliberate versioned migration.
3. Describe the answer space
Criteria are not decoration. They are the rubric that turns a vague classification into an interpretable decision. Explain what qualifies for each option, define the low and high ends of a score, and include a catch-all outcome when the real world has cases that do not fit the main categories.
4. Define policy outside the model
The model should not decide whether a user is authorized to delete an account, whether a payment is permitted, or whether a rate limit has been exceeded. Those are deterministic application responsibilities. Jev can provide a risk or intent signal before the gate, but your service must still enforce the gate.
The three Jev question types
The official Jev documentation describes three core question types. Choose the type that matches the decision’s geometry.

Choice: select from known alternatives
Use Choice when the output is one option from a defined set. Good examples include support-team routing, lead segmentation, document type, model selection, or content workflow status.
const questions = {
  department: {
    type: "choice",
    instructions: "Which team should handle this request?",
    criteria: {
      billing: "Payments, invoices, refunds, or payouts",
      technical: "Bugs, outages, or integration failures",
      sales: "Pricing, upgrades, or new accounts",
      needs_review: "The request does not clearly fit another option"
    }
  }
} as const;
The needs_review option is important. Without it, the model must choose the closest category even when none is a good fit. A complete answer space is often more valuable than a long prompt.
Score: rate an ordered property
Use Score when the concept has a meaningful low-to-high scale, such as urgency, severity, relevance, or customer frustration. The criteria are ordered levels. The returned score is probability-weighted, so it can fall between the named levels.
For example, a three-level urgency rubric could be routine, elevated, and critical. Define each level in terms of observable evidence and the action it should influence. Do not treat a score as a direct authorization. A score of 2.7 can recommend escalation; it cannot bypass an incident-management policy.
Noul: judge one yes-or-no proposition
Use Noul for one focused proposition: “Does this message explicitly request a refund?” or “Does this tool call involve an irreversible action?” The returned noul value is the probability that the answer is yes. It is not a second confidence field and should not be interpreted like a Choice distribution.
If your workflow needs a category, a severity score, and a yes/no check, send three clearly named questions against the same state. The application can combine them with ordinary Boolean logic and policy checks.
TypeScript types are not runtime validation
This is where many “TypeSafe AI” implementations fail. TypeScript checks the code you compile. It does not inspect the bytes returned by a remote server. This line is not validation:
const payload = (await response.json()) as JevResponse;
The cast changes what the compiler believes. It does not prove that payload.answers.department.choice exists, is a string, or belongs to your own allowlist.
Start at the network boundary with unknown, then validate the fields your policy consumes. A small hand-written guard is often enough for a focused integration:
type Decision = {
  team: "billing" | "technical" | "sales" | "needs_review";
  confidence: number;
  probabilities: Record<string, number>;
};

function asRecord(value: unknown): Record<string, unknown> | null {
  return typeof value === "object" && value !== null && !Array.isArray(value)
    ? (value as Record<string, unknown>)
    : null;
}

function parseDecision(value: unknown): Decision {
  const root = asRecord(value);
  const answers = asRecord(root?.answers);
  const answer = asRecord(answers?.department);
  const team = answer?.choice;
  const confidence = answer?.confidence;
  const probabilities = asRecord(answer?.probabilities);
  const allowed = ["billing", "technical", "sales", "needs_review"];

  if (
    typeof team !== "string" ||
    !allowed.includes(team) ||
    typeof confidence !== "number" ||
    !Number.isFinite(confidence) ||
    confidence < 0 ||
    confidence > 1 ||
    !probabilities
  ) {
    throw new Error("Unexpected Jev response shape");
  }

  const values = Object.values(probabilities);
  if (!values.every((item) => typeof item === "number" && item >= 0 && item <= 1)) {
    throw new Error("Invalid probability map");
  }

  return {
    team: team as Decision["team"],
    confidence,
    probabilities: probabilities as Record<string, number>
  };
}
For a production service, use the same principle for every field that can influence an action. Validate the response type, required keys, numeric ranges, probability totals, and allowed identifiers. Treat validation failure as an unavailable decision, not as a low-confidence negative answer.
A production architecture for Jev AI
Jev works best as a narrow decision layer inside a larger system. A useful architecture has four stages:
- A generative LLM or application service gathers context and creates a bounded question.
- Jev evaluates that state against typed questions in parallel.
- A deterministic policy layer validates the response, checks permissions, and applies thresholds.
- The application takes an action, asks for confirmation, or sends the case to a review queue.
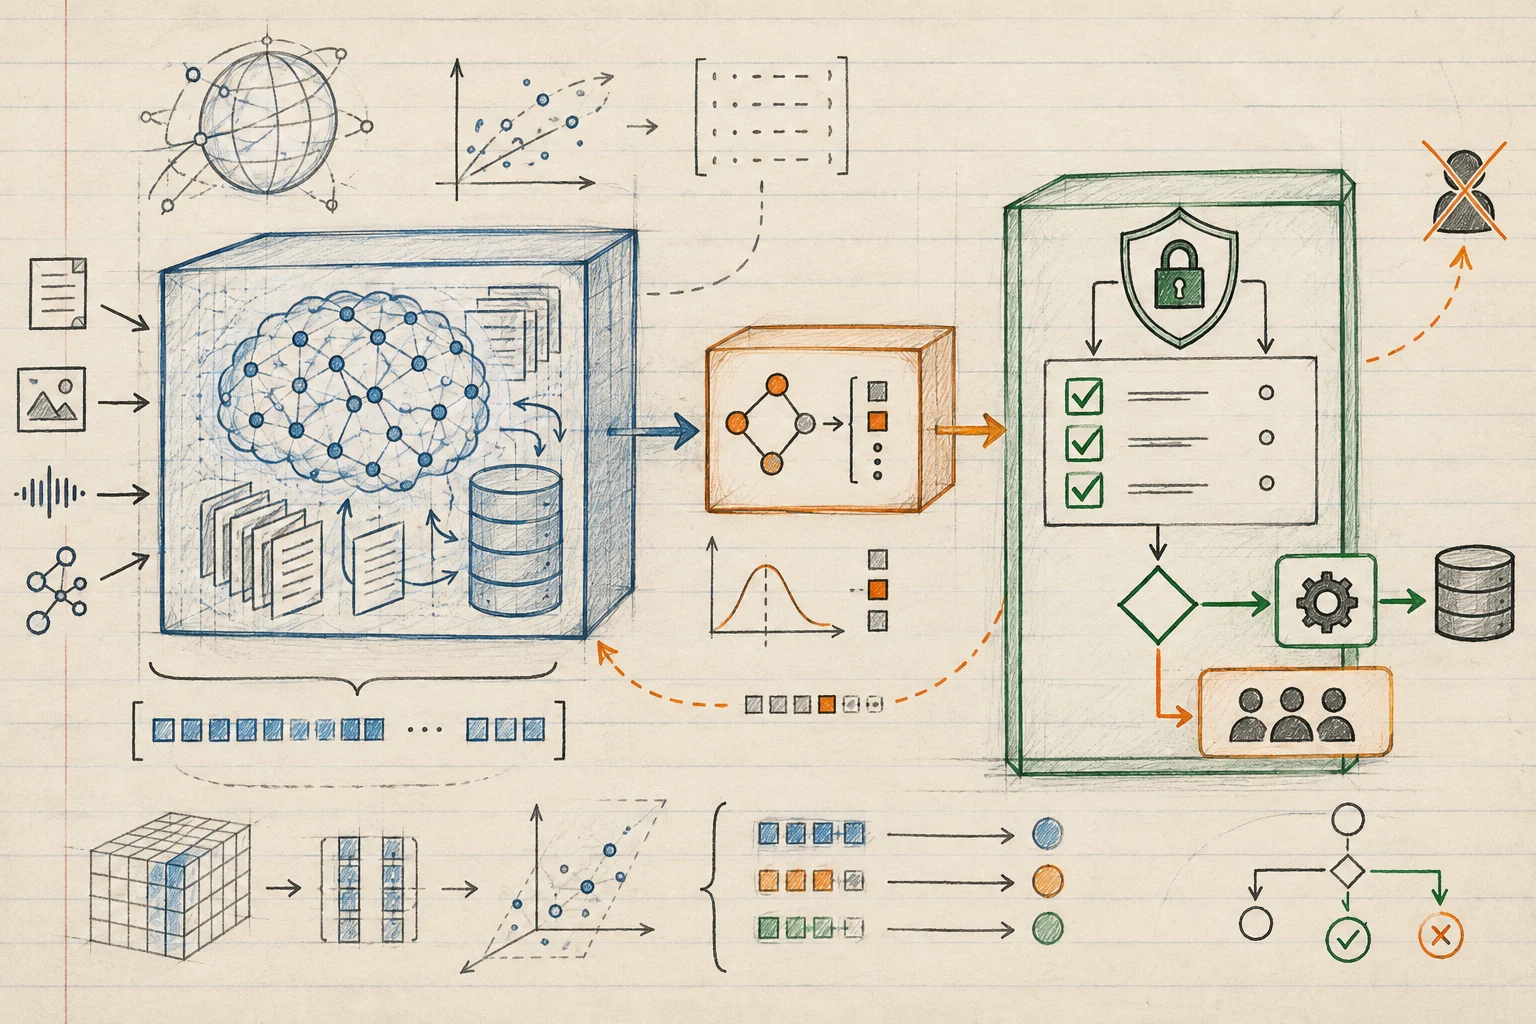
This separation prevents a common failure mode: allowing a broad language model to both interpret a request and directly execute a sensitive action. The LLM can hold context and produce a proposed task. Jev can judge a bounded property such as “is this tool call risky?” The application still owns the API key, authorization, idempotency, rate limit, confirmation step, and final execution.
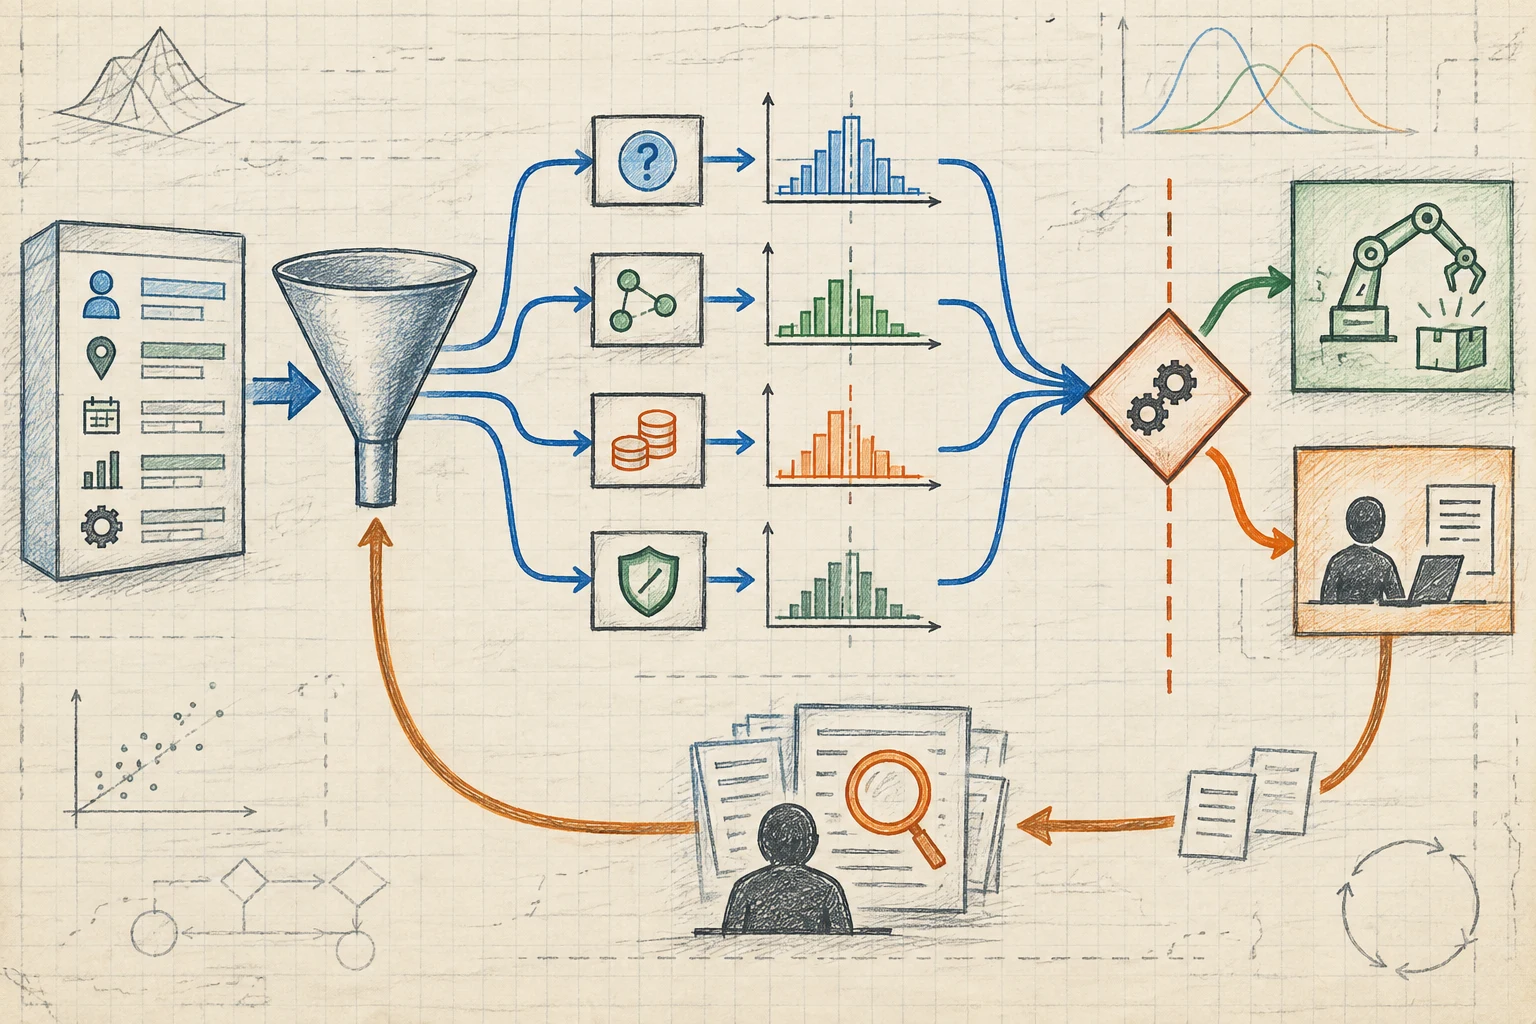
The basic REST boundary is straightforward. The docs show the POST https://thejevai.com/v1/systemone endpoint with a Bearer API key, a model such as jev-latest, a state, and a questions map. Keep the call on your server. Do not embed JEV_API_KEY in browser code or send it to an agent transcript.
Model the result internally as more than a Boolean:
type WorkflowResult<T> =
  | { kind: "decision"; value: T; confidence?: number }
  | { kind: "review"; reason: string }
  | { kind: "unavailable"; reason: string };
This distinction matters operationally. A ticket classified as “billing” is not the same as a timeout. A tool call that could not be evaluated is not the same as a safe tool call. Explicit states make fallbacks visible in metrics and prevent transport failures from becoming accidental approvals.
High-value use cases
Support and operations routing
Classify department, score urgency, and judge whether a human is needed in one request. Use the selected route only after validating it against a server-side allowlist. Keep escalation rules explicit so that a critical incident cannot be hidden by a confident but wrong category.
Model routing
Use a small decision before calling an expensive generative model. A Choice question can select fast, balanced, or reasoning; a Score question can estimate task difficulty. The application can then choose a provider, enforce a budget, and record why the route was selected.
Tool-call safety
Before an agent executes a tool, ask a narrow Noul question such as whether the request contains an irreversible action. If yes, require explicit confirmation or a human review. Still perform deterministic checks for authentication, authorization, resource ownership, and input constraints.
Content and lead workflows
Jev can help sort content into a known editorial queue, score lead urgency, or flag a message for review. Keep the criteria versioned and measure performance by segment. A global average can hide poor behavior on a high-value customer group or a rare safety category.
Context compaction and memory selection
Long-running agents often need to decide which facts remain relevant after a context window is compressed. A Choice or Score question can help rank tool results for retention. Store the source and reason for retention; do not let a probability signal erase the only copy of a critical fact.
How to use probability and confidence
Probability and confidence are signals, not guarantees of correctness. The Jev Playground is useful for exploring representative states and seeing the response shape before you connect an API key to production.
Choose thresholds from a labeled evaluation set, not from a tutorial. Include ordinary cases, borderline cases, rare cases, adversarial wording, and examples that should select needs_review. Measure the business cost of each error:
- A false escalation may waste a reviewer’s time.
- A missed outage may affect every customer.
- A wrong model route may increase latency or cost.
- An unsafe tool decision may create an irreversible incident.
Use different thresholds for different actions. A low-risk content tag may auto-apply at a modest threshold. A payment, account restriction, deletion, or production deployment should require stronger evidence and deterministic gates even when confidence is high.
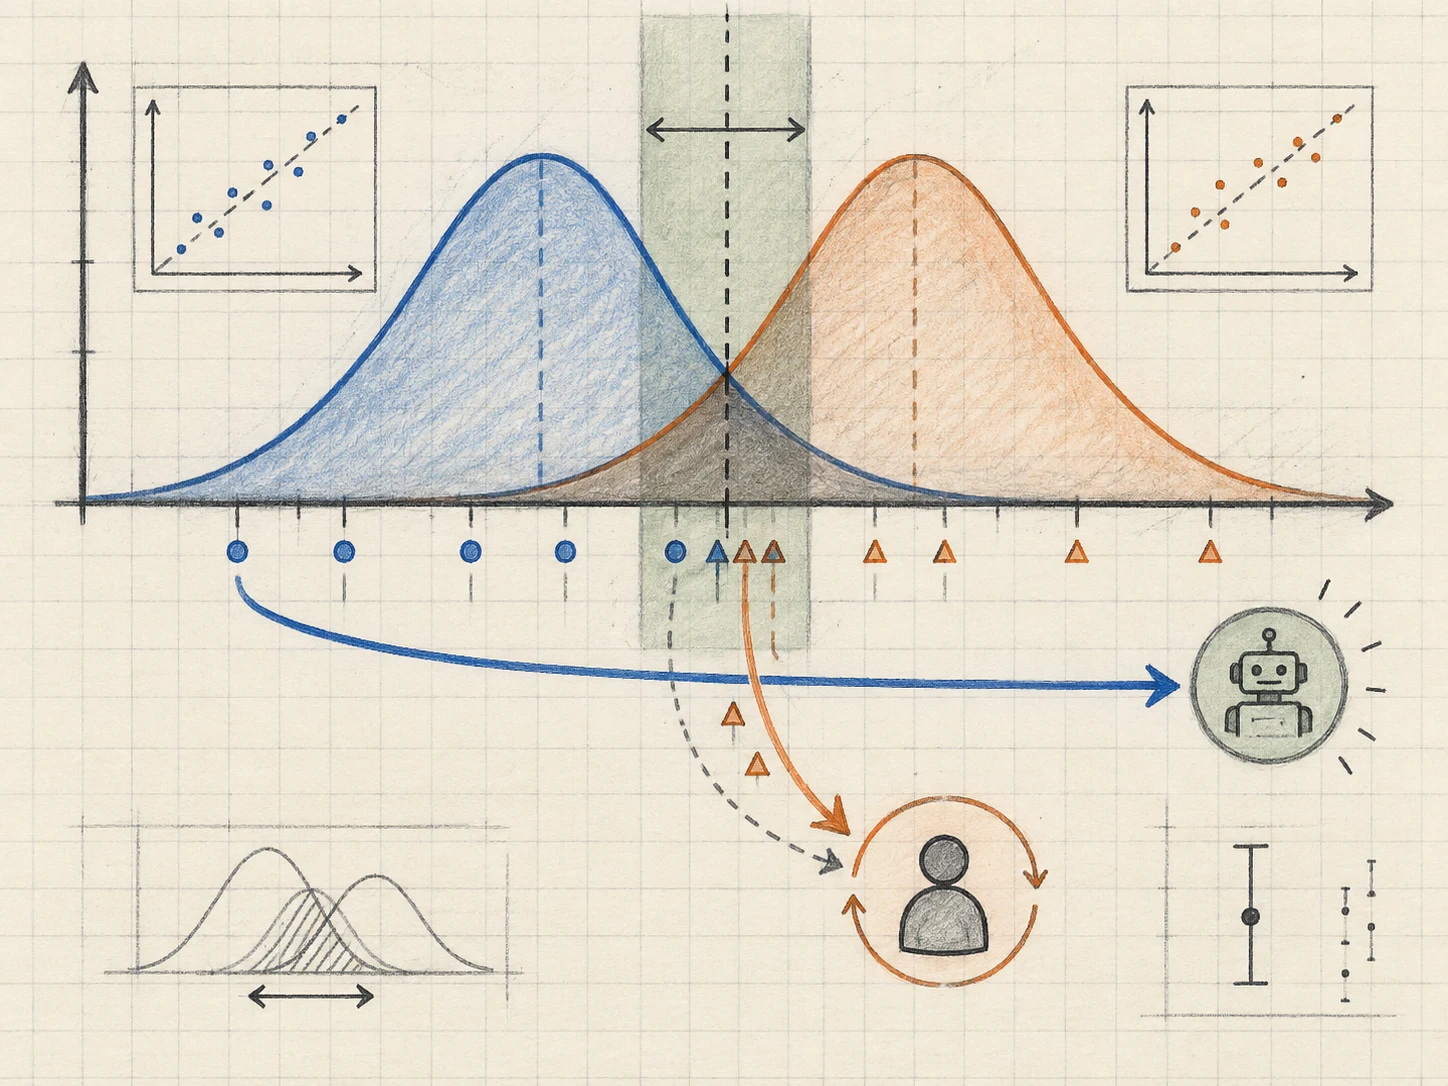
Monitor more than confidence: selected answer, probability margin, input segment, human correction, escalation rate, downstream outcome, latency, and unavailable rate. If the input distribution changes, a threshold that worked last month may no longer be appropriate.
Security, privacy, and operational boundaries
Keep API keys in server-side environment variables or a secret manager. Redact keys from logs, error messages, browser bundles, and support tickets. Send only the state required for the defined question. If state includes personal or confidential information, decide retention, access control, encryption, and deletion before launch.
Use bounded timeouts. Retry only transient failures, respect server retry guidance, and cap attempts. Do not retry a schema-validation failure as if it were a network failure. After the retry budget is exhausted, route to a known safe queue or ask for a human decision.
Version the questions and criteria alongside the code that interprets the answer. If you rename a category, change what “critical” means, or add a review path, update the evaluation set and compare the new version against the old one. Logging the question version is often more useful than logging a large raw prompt.
At the time of writing, the public docs describe text, JSON objects, and arrays of text as the input boundary and say that image, audio, and video inputs are not supported yet. If your product starts with multimodal data, preprocess it into a justified text or structured representation and evaluate that preprocessing separately.
A rollout plan and checklist
Start small. Pick one decision with a clear answer space and a safe fallback.
- Explore: Use a real but sanitized sample in the Playground. Rewrite vague criteria until another engineer can apply them consistently.
- Evaluate offline: Create a labeled set with normal, ambiguous, rare, and high-cost cases. Record both model signals and business outcomes.
- Shadow: Call Jev while the existing workflow remains authoritative. Compare its proposed decision with the human or rules-based result.
- Assist: Show the suggestion to an operator, collect corrections, and inspect where the rubric is incomplete.
- Automate selectively: Enable only low-risk branches that meet measured thresholds and have a pause switch.
- Review continuously: Monitor drift, unavailable responses, correction rates, and cost. Re-run the evaluation set when criteria or input sources change.
Before launch, verify that:
- the state excludes irrelevant secrets and personal data;
- every question has one stable ID and one clear purpose;
- the answer space includes a safe fallback;
- remote JSON is parsed from
unknownand checked at runtime; - the policy layer owns authorization and irreversible actions;
- thresholds are tied to measured error costs;
- network failures and validation failures have separate outcomes;
- API keys stay server-side;
- question and criteria versions are observable.
For access, usage limits, and current plan details, review the Jev AI pricing page directly rather than copying a number from an old article.
When Jev is not the right tool
Do not force every AI feature into a typed decision model. A generative LLM is a better fit when the primary output is a long explanation, a draft, a translation, or an open-ended conversation. A deterministic rule is better when the condition is already fully known and must be exact. A traditional classifier or local model may be better when data residency, offline operation, or full infrastructure control is the primary requirement.
Jev is most valuable in the middle: the input is messy enough to need semantic judgment, but the output is constrained enough to fit a business decision. That boundary is where a model can be helpful without becoming the owner of your product’s permissions and side effects.
Frequently asked questions
Is Jev AI the same thing as TypeSafe AI?
Treat them as related terms, not interchangeable names. Jev AI is the decision product described on the public site. The site explicitly says it is independently operated and not affiliated with, operated by, or endorsed by TypeSafe. Verify current product and organization details on the official pages before making a branding or integration assumption.
Does “typed” guarantee that an answer is correct?
No. A typed response makes the interface easier to validate and evaluate. It does not guarantee semantic accuracy, calibrated probability, or business correctness. Keep evaluation data, thresholds, deterministic checks, and human review where risk warrants it.
Can Jev replace a large language model?
Not for every task. Jev is designed for bounded decisions such as classification, routing, scoring, and safety checks. Use a generative model for open-ended text, then use a typed decision layer when your application needs a specific judgment before acting.
Should I send the entire user record as state?
Usually no. Send the smallest text or structured object that contains the evidence needed for the question. Smaller state improves privacy, reviewability, and reproducibility.
What should happen when Jev is unavailable?
Represent unavailability explicitly. Depending on the workflow, pause the action, keep the existing rules-based route, or send the case to a human queue. Never silently treat a timeout as “no” or choose the first option in a list.
What is the best first Jev AI TypeSafe AI project?
Choose a frequent, bounded, reversible decision with a measurable outcome: support routing, lead prioritization, model selection, or tool-call review. Start in shadow mode, validate the response at runtime, and automate only after the measured error cost is acceptable.
Conclusion
The practical idea behind jev ai typesafe ai is not a new spelling of “ask an LLM for JSON.” It is a disciplined boundary: give the model relevant state, ask one or more explicit typed questions, inspect structured signals, and keep policy and execution in application code.
When you use Jev this way, TypeScript can describe the internal contract, runtime validation can protect the network boundary, and evaluation can tell you whether the decision is useful in the real world. The result is a workflow that is faster to test, easier to monitor, and safer to evolve than an opaque prompt whose text happens to look like a schema.