Developer Guides
Jev TypeSafe: Add Typed Decisions to TypeScript
A practical guide to Jev TypeSafe workflows: define typed questions, validate API responses at runtime, and route uncertain decisions safely in TypeScript.
Searches for jev typesafe often point to two related but different ideas: Jev’s typed AI decisions and TypeScript’s type system. This guide shows how to connect them without confusing a compile-time type with a trustworthy runtime result. Jev evaluates questions about a piece of state and returns structured answers; your TypeScript service still validates the network response and decides what the application may do.
Jev’s site describes it as an independent decision tool for software teams. It is not affiliated with, operated by, or endorsed by TypeSafe. If you want to see the product first, try the Jev AI homepage and its online Playground.
What “type-safe Jev” means in a TypeScript application
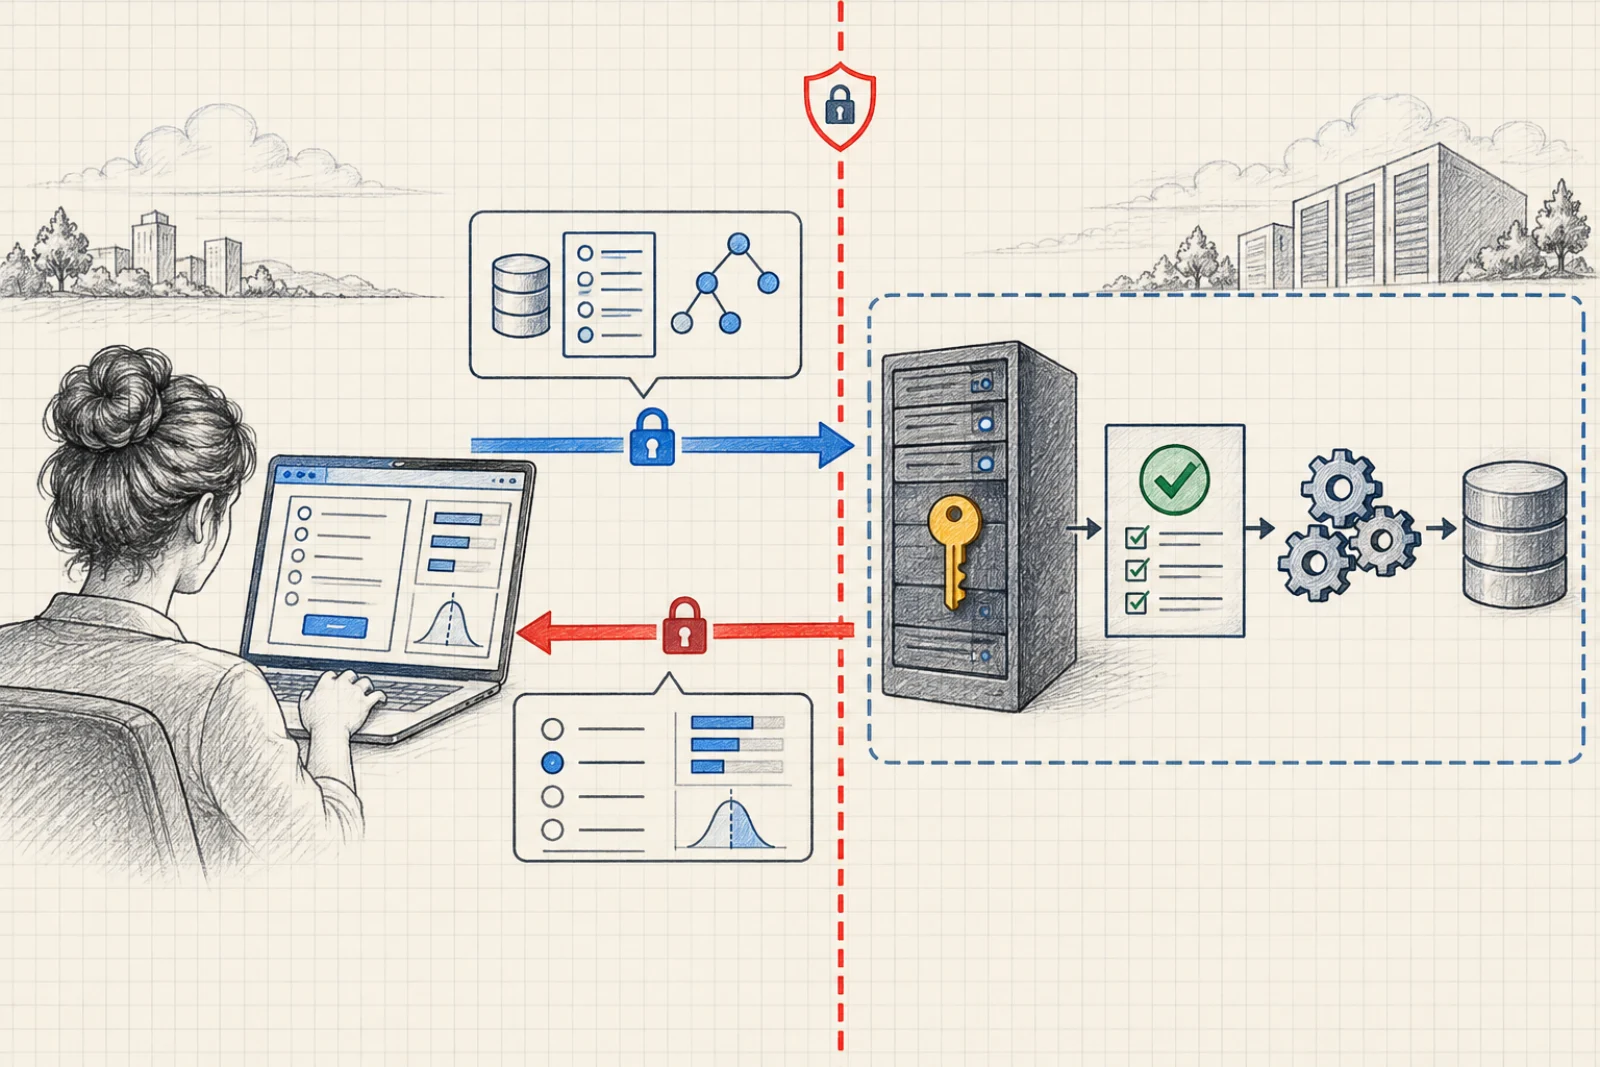
TypeScript checks your code before it runs. It can catch mistakes such as a misspelled property or a function receiving the wrong internal type. It cannot prove that an HTTP response from a remote service matches a type you wrote. A declaration such as const answer: Decision = await response.json() only tells the compiler what you hope the server returned. It does not inspect the bytes that arrived.
Treat data from response.json() as unknown until the application checks its shape. The useful boundary has two parts:
- Request construction: TypeScript can keep your state, question definitions, and internal identifiers consistent.
- Response parsing: runtime checks confirm that the remote data contains the fields your code plans to read.
That distinction matters because a model response is a decision signal, not authorization to perform an action. Your application remains responsible for authentication, business constraints, deterministic checks, and any required approval.
Start with Jev’s three question types
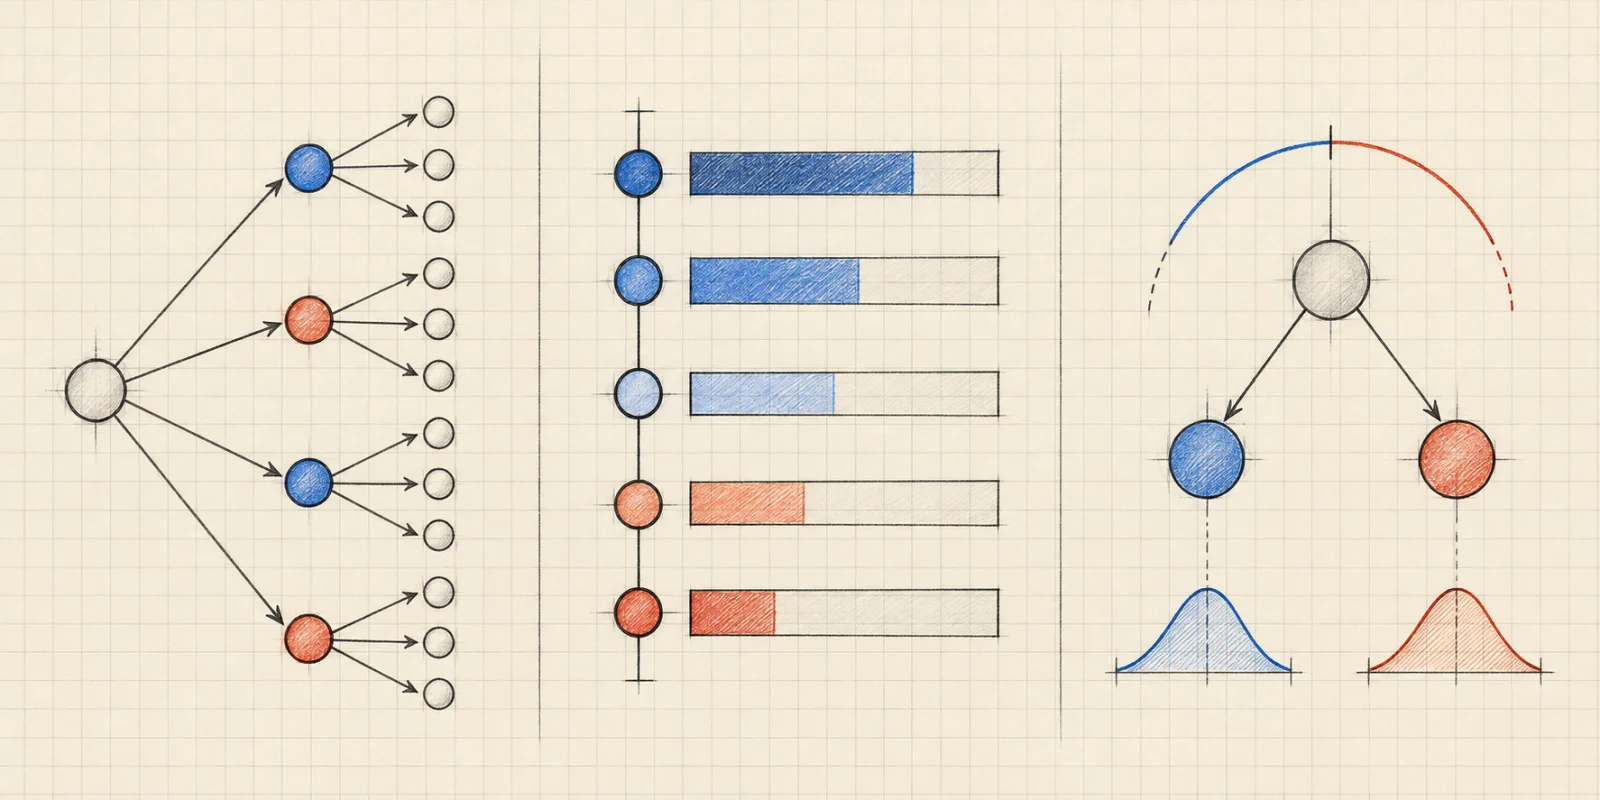
The Jev documentation describes three question shapes. Match the type to the shape of the decision instead of asking one broad prompt to do several unrelated jobs.
| Type | Good fit | Result to inspect |
|---|---|---|
| Choice | Team, queue, category, or model selection | Selected option, probabilities, confidence |
| Score | Severity, quality, urgency, or another ordered scale | Weighted score, level probabilities, confidence |
| Noul | Whether one focused proposition is true | Probability from 0 to 1 that the answer is yes |
Use Choice when the possible outcomes are known. If a support ticket can go to billing, technical support, or sales, define what qualifies for each option. Include a safe other or needs_review option when the list is not exhaustive; otherwise a classifier must choose the nearest imperfect match.
Use Score when the answer has an order. Describe levels from low to high and make the descriptions concrete. A severity rubric might define what “low,” “moderate,” and “critical” mean for response time or escalation. Jev returns a probability distribution and a probability-weighted score, so a result can fall between named levels. Your code should still map that number to an explicit business policy.
Use Noul for one yes-or-no proposition, such as whether a message contains a refund request. Its noul value is the probability that the answer is yes. It is not a second confidence field. If the workflow needs both a category and a yes-or-no condition, use two question IDs and inspect both answers.
Design the decision before writing the request
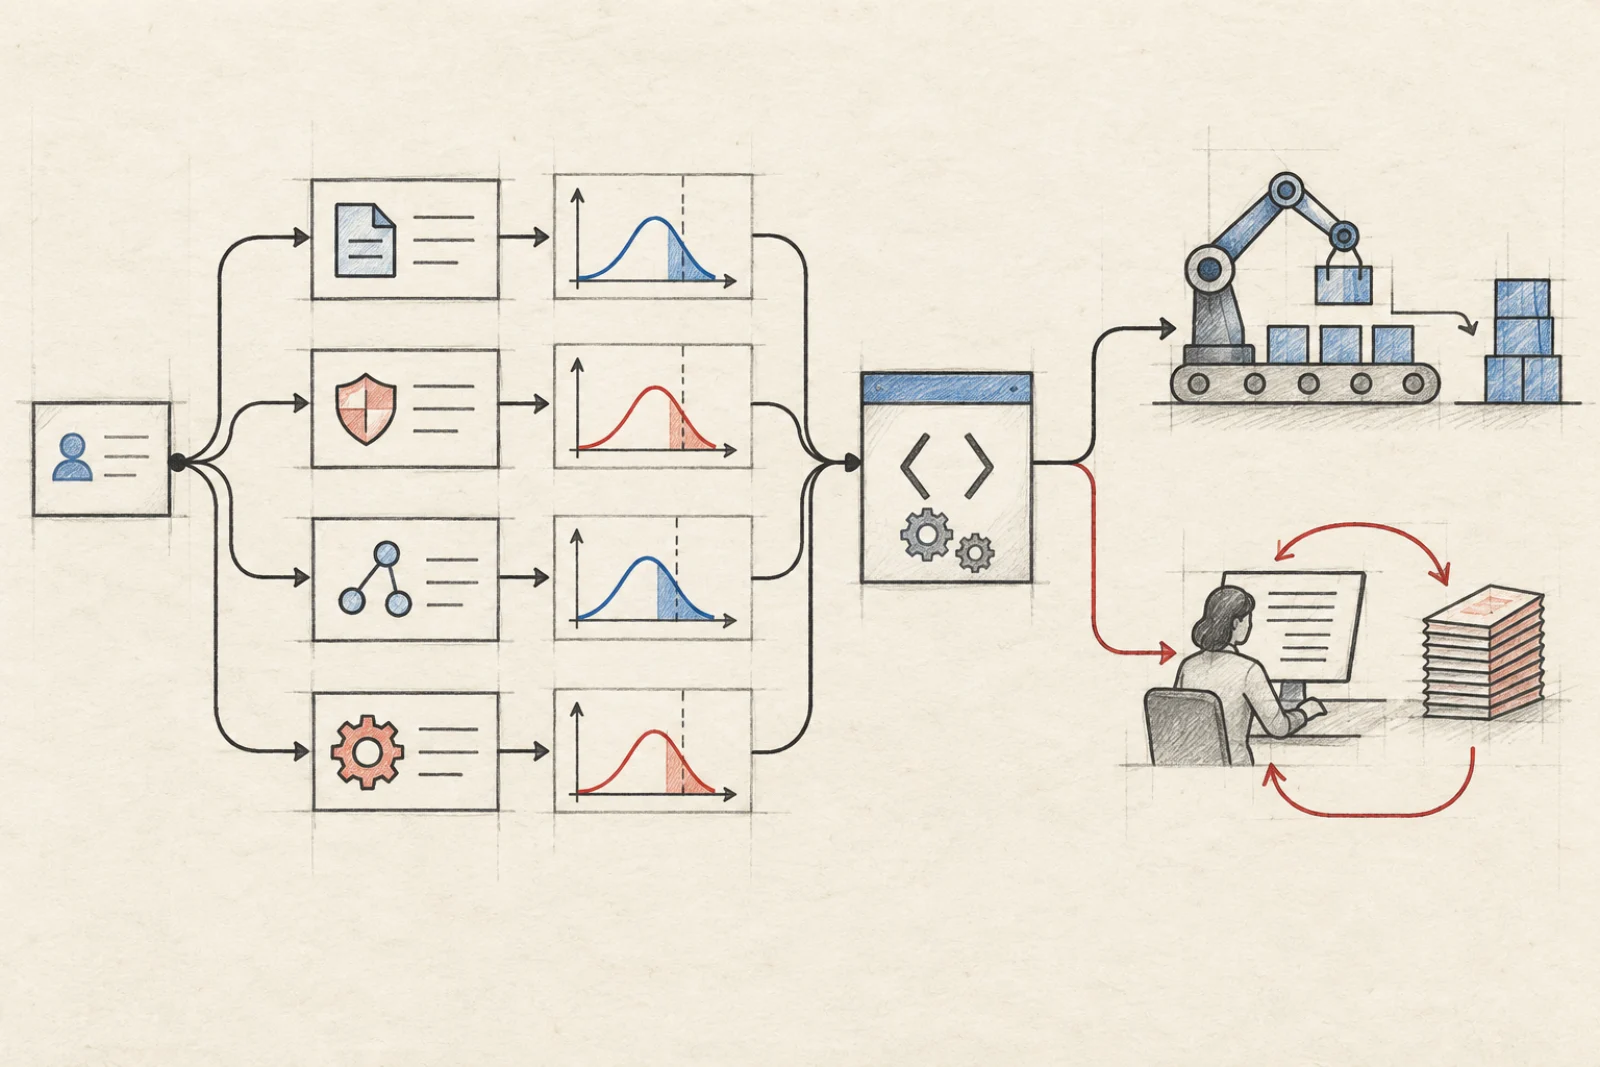
A reliable integration starts with a small decision contract. Write down the exact action your application may take, the possible answers, what evidence belongs in the input, and what should happen when the result is uncertain. This often reveals that a proposed “AI task” is actually two or three independent questions.
For example, a support workflow might ask Jev to select a team, score urgency, and judge whether the message explicitly requests a refund. Those questions can share the same state and be evaluated in one request. Give each a stable key such as department, urgency, and refund_requested; the keys are how your code finds the corresponding results. Keep them stable when you rename a label shown to an operator.
Make the state sufficient but not bloated. A ticket-routing decision may need the message, product area, and account tier. It probably does not need a full customer profile, unrelated conversation history, or secrets. Smaller, relevant state is easier to review, cheaper to transmit, and less likely to expose data that has no bearing on the decision.
Jev accepts text, JSON objects, and arrays of text as state. Use a string for a simple message and a structured object when fields have distinct meanings. Arrays can hold related text items, such as a current message and a short policy excerpt. Images, audio, and video are not direct inputs in the documented boundary; preprocess them with OCR, transcription, or another service before including relevant text.
Build a typed request and validate the response
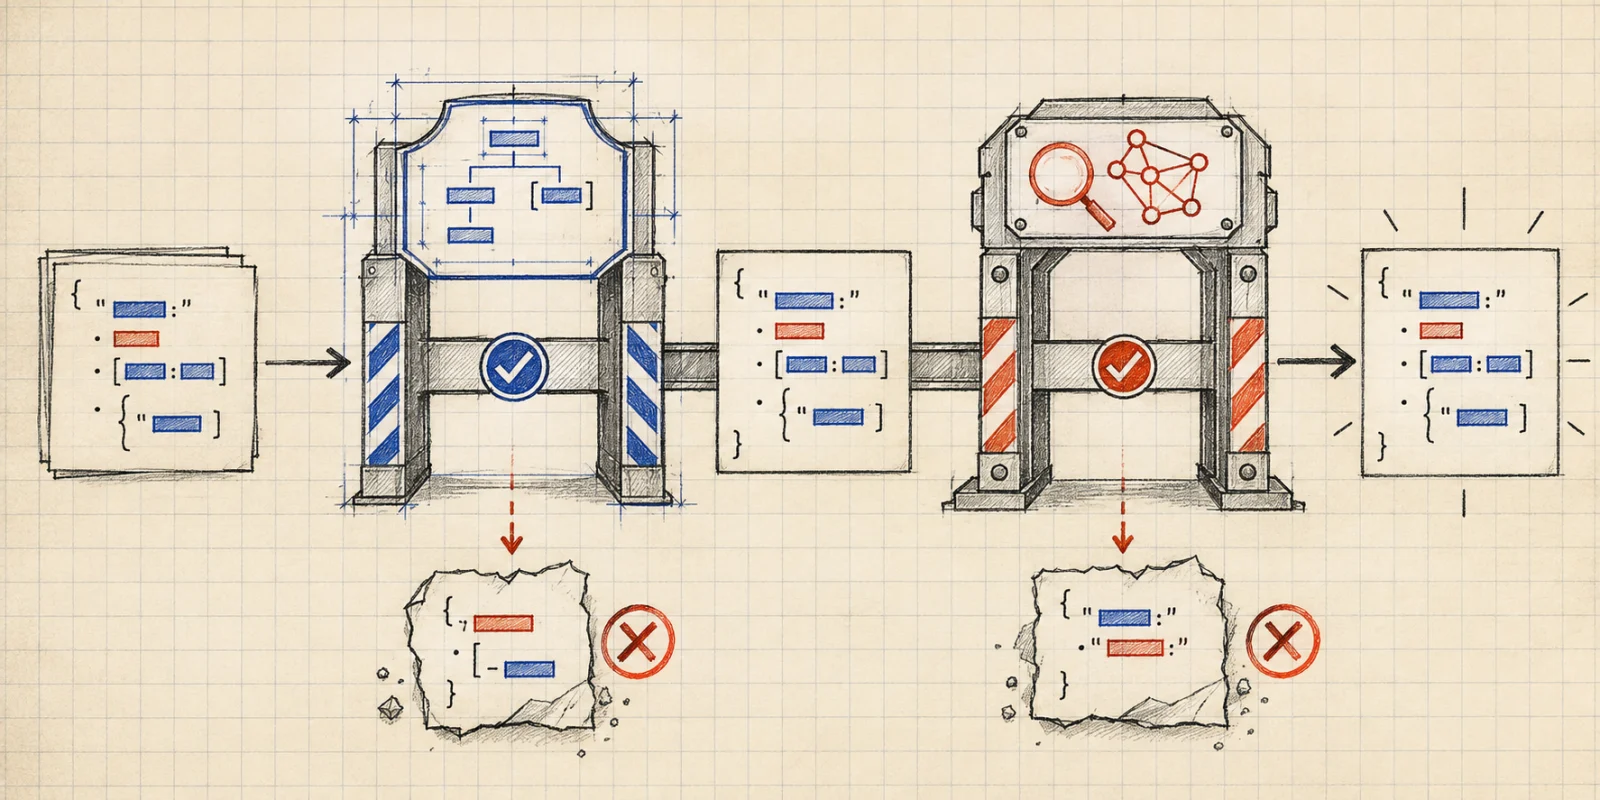
The example below calls the documented System One endpoint from a server-side TypeScript service. The request type catches mistakes while your code is being written. The response remains unknown until runtime checks validate the fields this workflow actually consumes.
type Question =
  | { type: "choice"; instructions: string; criteria: Record<string, string> }
  | { type: "score"; instructions: string; criteria: string[] }
  | { type: "noul"; instructions: string };

type EvaluationRequest = {
  model: "jev-latest";
  state: string | Record<string, unknown> | string[];
  questions: Record<string, Question>;
};

function asRecord(value: unknown): Record<string, unknown> | null {
  return typeof value === "object" && value !== null && !Array.isArray(value)
    ? (value as Record<string, unknown>)
    : null;
}

function isProbabilityMap(value: unknown): value is Record<string, number> {
  const map = asRecord(value);
  if (!map) return false;
  const entries = Object.values(map);
  if (entries.length === 0) return false;
  if (!entries.every(
    (item) => typeof item === "number" && Number.isFinite(item) && item >= 0 && item <= 1
  )) return false;
  const total = entries.reduce((sum, item) => sum + item, 0);
  return Math.abs(total - 1) < 0.02;
}

async function classifyTicket(ticket: string) {
  const apiKey = process.env.JEV_API_KEY;
  if (!apiKey) throw new Error("JEV_API_KEY is not configured");

  const request = {
    model: "jev-latest",
    state: { message: ticket },
    questions: {
      department: {
        type: "choice",
        instructions: "Which team should handle this ticket?",
        criteria: {
          billing: "Payments, invoices, refunds, or payouts",
          technical: "Bugs, outages, or integration failures",
          sales: "Pricing, upgrades, or new accounts"
        }
      }
    }
  } satisfies EvaluationRequest;

  const response = await fetch("https://thejevai.com/v1/systemone", {
    method: "POST",
    headers: {
      Authorization: "Bearer " + apiKey,
      "Content-Type": "application/json"
    },
    body: JSON.stringify(request)
  });

  if (!response.ok) throw new Error("Jev request failed: " + response.status);

  const payload: unknown = await response.json();
  const root = asRecord(payload);
  const answers = asRecord(root?.answers);
  const answer = asRecord(answers?.department);

  if (
    answer?.type !== "choice" ||
    typeof answer.choice !== "string" ||
    typeof answer.confidence !== "number" ||
    !Number.isFinite(answer.confidence) ||
    answer.confidence < 0 ||
    answer.confidence > 1 ||
    !isProbabilityMap(answer.probabilities)
  ) {
    throw new Error("Unexpected Jev response shape");
  }

  const allowedTeams = ["billing", "technical", "sales"];
  if (!allowedTeams.includes(answer.choice)) {
    throw new Error("Jev returned an unrecognized team");
  }

  return {
    team: answer.choice,
    confidence: answer.confidence,
    probabilities: answer.probabilities
  };
}

const result = await classifyTicket("Three deploys failed and production is returning 500s.");
if (result.confidence >= 0.8) {
  // Apply an allowlist and business rules before routing.
} else {
  // Send uncertain cases to a human-review queue.
}
This example is intentionally narrow. It validates the shape used by the department-routing branch, checks that probability values are finite and within range, and rejects a choice outside the application’s own allowlist. A larger application should validate every field that influences an action. If a field is informational only, do not let its presence silently become a control signal.
Keep JEV_API_KEY in a server-side secret store. Never place it in a browser bundle, a public repository, an error message, or analytics properties. A TypeScript type does not hide a value from users if the code containing it is shipped to the browser.
Read the answer shape without over-trusting it
The response is organized by the question IDs you sent. For Choice, inspect the selected option, the probabilities for the available options, and confidence. For Score, inspect the probability-weighted score, its legend, the level probabilities, and confidence. For Noul, inspect the yes probability. Validate the shape that corresponds to the question type instead of assuming every answer has the same fields.
A response can be structurally valid and still be wrong for a particular business case. Runtime validation answers “Can my code safely read this value?” Evaluation answers “Does this workflow make good decisions on representative inputs?” Those are separate checks and both matter.
Avoid collapsing all signals into one generic success boolean. Preserve the typed result long enough for application policy to use the right field. A route may depend on the selected Choice and a confidence threshold; a prioritization queue may use Score; a confirmation step may depend on Noul. Explicit mappings make later review and debugging easier.
Use confidence as a signal, not a guarantee
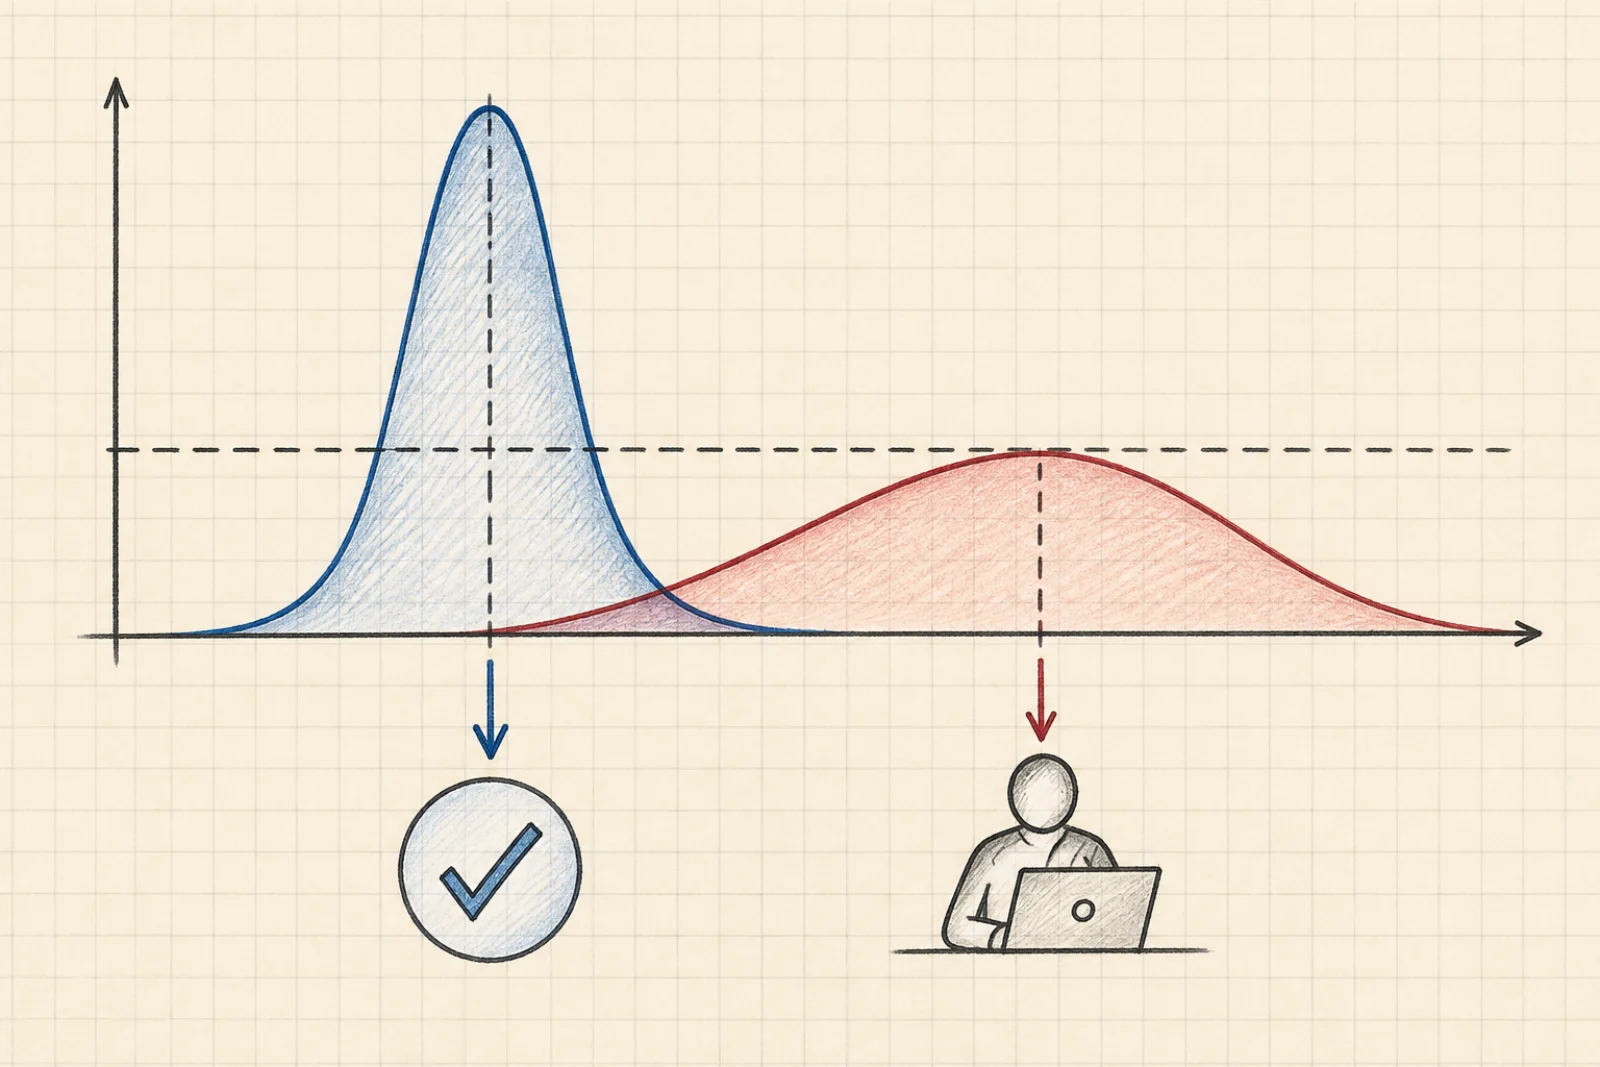
Jev returns probabilities for Choice and Score answers, along with a confidence signal; Noul returns a yes probability. These values help compare or route cases, but they do not prove that a decision is correct. Confidence is not the same as measured accuracy, and a high number is not a safety guarantee.
Build a labeled evaluation set from examples that resemble the real input mix. Include routine cases, borderline cases, rare but costly cases, and examples that should map to other or human review. Measure errors by outcome, not only with one aggregate accuracy number. Sending an urgent outage to a low-priority queue may be more expensive than escalating a routine request unnecessarily.
Choose thresholds from observed behavior and the cost of mistakes. For a low-impact suggestion, a lower threshold may be acceptable if a person can easily correct it. For a payment, account restriction, or destructive operation, keep deterministic checks and human approval even when model confidence is high. Do not copy a threshold from a tutorial and treat it as a universal default.
Handle failures and uncertain results as normal paths
A production request can fail before Jev returns an answer: the network may time out, the service may return a non-success status, or the body may not parse as expected. Model those outcomes explicitly. A useful internal result type might distinguish decision, review, and unavailable, so a transport problem cannot accidentally look like an ordinary negative answer.
Use bounded timeouts and retries appropriate to the operation. Retry only errors that are plausibly transient, respect any server-provided retry guidance, and cap the number of attempts. Do not retry validation failures as though they were network glitches. If the decision is unavailable after the retry budget, fall back to a known safe queue or review path instead of silently selecting the first option.
Log enough to diagnose the workflow: request correlation identifiers if available, question IDs, response status, validation outcome, and the policy branch selected. Avoid storing API keys or unnecessarily copying raw personal data into logs. If the original state is needed for audit, define retention, access controls, and redaction deliberately.
Roll out in stages
A gradual rollout helps separate model quality from integration bugs:
- Explore: Try representative states and typed questions in the Jev Playground. Refine unclear criteria before writing production code.
- Evaluate offline: Run a labeled sample through the request path. Review confusion patterns and the cases with the highest business cost.
- Shadow: Send requests for observation while the existing workflow remains authoritative. Compare proposed answers with actual outcomes without taking action.
- Assist: Show suggestions to an operator and collect corrections. This exposes missing categories and confusing rubrics.
- Automate selectively: Enable only the branches that meet your measured threshold and have a safe fallback. Keep a way to pause automation when input patterns change.
Version your question wording and criteria alongside the code that interprets the result. If you change the meaning of critical or add a destination team, your evaluation set should cover the new behavior before rollout. Monitor changes in input mix, corrections, escalation rates, and downstream outcomes; a stable response schema does not guarantee stable performance.
Common integration mistakes
Trusting a TypeScript cast. A cast changes what the compiler believes, not what the server sent. Parse from unknown, validate the fields used, and reject unexpected result types.
Asking compound questions. “Choose a team, decide urgency, and determine refund eligibility” bundles separate judgments. Use clear question IDs and combine the answers in ordinary code. Keep hard eligibility rules deterministic.
Forcing a choice when none fits. Incomplete criteria encourage a nearest-match answer. Add a catch-all outcome or route uncertain cases to review.
Treating probability as permission. A probability is evidence for a policy, not the policy itself. Authentication, authorization, rate limits, and irreversible-action checks belong to your service.
Sending the whole record. More context is not automatically better. Include only information needed to answer the defined questions, especially when state contains personal or confidential data.
A production checklist for Jev TypeSafe integrations
- Keep the API key in a server-side secret store and rotate it according to your organization’s policy.
- Send only relevant text or structured fields; remove unrelated personal data and secrets.
- Test routine, ambiguous, adversarial, and out-of-scope examples in the Playground and an offline evaluation set.
- Validate response type, required fields, ranges, probability totals, and application allowlists.
- Define timeouts, bounded retries, non-success handling, and a safe fallback path.
- Log validation and policy outcomes without logging credentials or unnecessary sensitive state.
- Review thresholds and question criteria as the input distribution and business costs change.
For current request and response fields, use the Jev API documentation. Review plans and usage before estimating production volume.
Frequently asked questions
Is Jev TypeSafe the same as TypeScript?
No. Jev returns typed decision outputs such as a choice, score, or yes probability. TypeScript checks your application code before it runs. A robust integration uses both: type the request and your internal result, then validate untrusted network data at runtime.
Does a TypeScript type validate an API response?
No. Type annotations are removed when JavaScript runs. Treat the decoded response as unknown and check each field your application relies on before routing, storing, or displaying it. A type guard can make the validated part safe to use afterward.
Can several questions use the same state?
Yes. Jev supports multiple typed questions for one state, evaluated in parallel. Keep each question atomic and give it a stable key so your code can read its answer independently. Separate questions are easier to test and combine than one prompt asking for a large nested decision.
Is Noul confidence?
No. Noul is the probability that a proposition is true. Choice and Score include confidence along with their answer probabilities. Read the field that matches the question type and design your own thresholds from measured examples.
Can Jev perform the action after deciding?
Your application should own execution. Use Jev to evaluate a bounded question; let your authorization checks, allowlists, deterministic rules, and approval steps decide whether to proceed. This keeps an uncertain model answer from becoming an unchecked side effect.
What is a good first use case?
Choose a repeated, low-impact decision with a small answer space, such as suggesting a support team. Make a labeled sample, define what each outcome means, and decide how unknown cases should be handled. Once the workflow is measurable, add runtime validation and compare suggestions with the existing process before automating.
Summary
The practical meaning of jev typesafe is a clear boundary between a model’s structured decision and the application logic that consumes it. Define narrow questions, send only relevant state, validate every response at runtime, measure behavior on representative examples, and keep uncertain or consequential cases on an explicit review path. TypeScript makes your own code easier to reason about; runtime checks protect it from untrusted data.