Uncategorized
How to Build More Reliable AI Agents with Jev AI: Routing, Guardrails, and Human Review
An AI agent should not let one language model decide everything. Learn how Jev AI can handle model routing, pre-tool safety checks, risk scoring, and human review while code keeps control of execution.
How to Build More Reliable AI Agents with Jev AI: Routing, Guardrails, and Human Review
The hard problem in an AI agent is often not “can the model answer?” It is whether the agent should act in the current state. An agent may need to choose a model, call a tool, request more information, pause, or hand the task to a person.
When every decision belongs to one generative LLM, planning, execution, and safety review become tangled. The model may produce a plausible explanation without providing a stable control signal, and it becomes difficult to tell whether a failure came from understanding, authorization, a tool, or a threshold.
Jev AI can act as an independent decision layer for an agent: receive the current State, ask small Choice, Score, or Noul questions, and return probability and confidence signals to orchestration code. The agent executes, Jev judges, and rules plus people provide the safety net.
This guide presents a practical agent architecture for model routing, pre-tool guardrails, risk scoring, human review, and production evaluation.
Core principle: Do not let one model own understanding, decision, authorization, and execution at the same time. Break judgment into testable questions and keep the final action in constrained code.
Table of contents
- Why agents need a decision layer
- Where Jev AI fits
- Pattern 1: route the model before calling
- Pattern 2: guard tool calls
- Pattern 3: use probability to trigger review
- Designing agent State and questions
- Security and evaluation checklist
- Frequently asked questions
Why agents need a decision layer
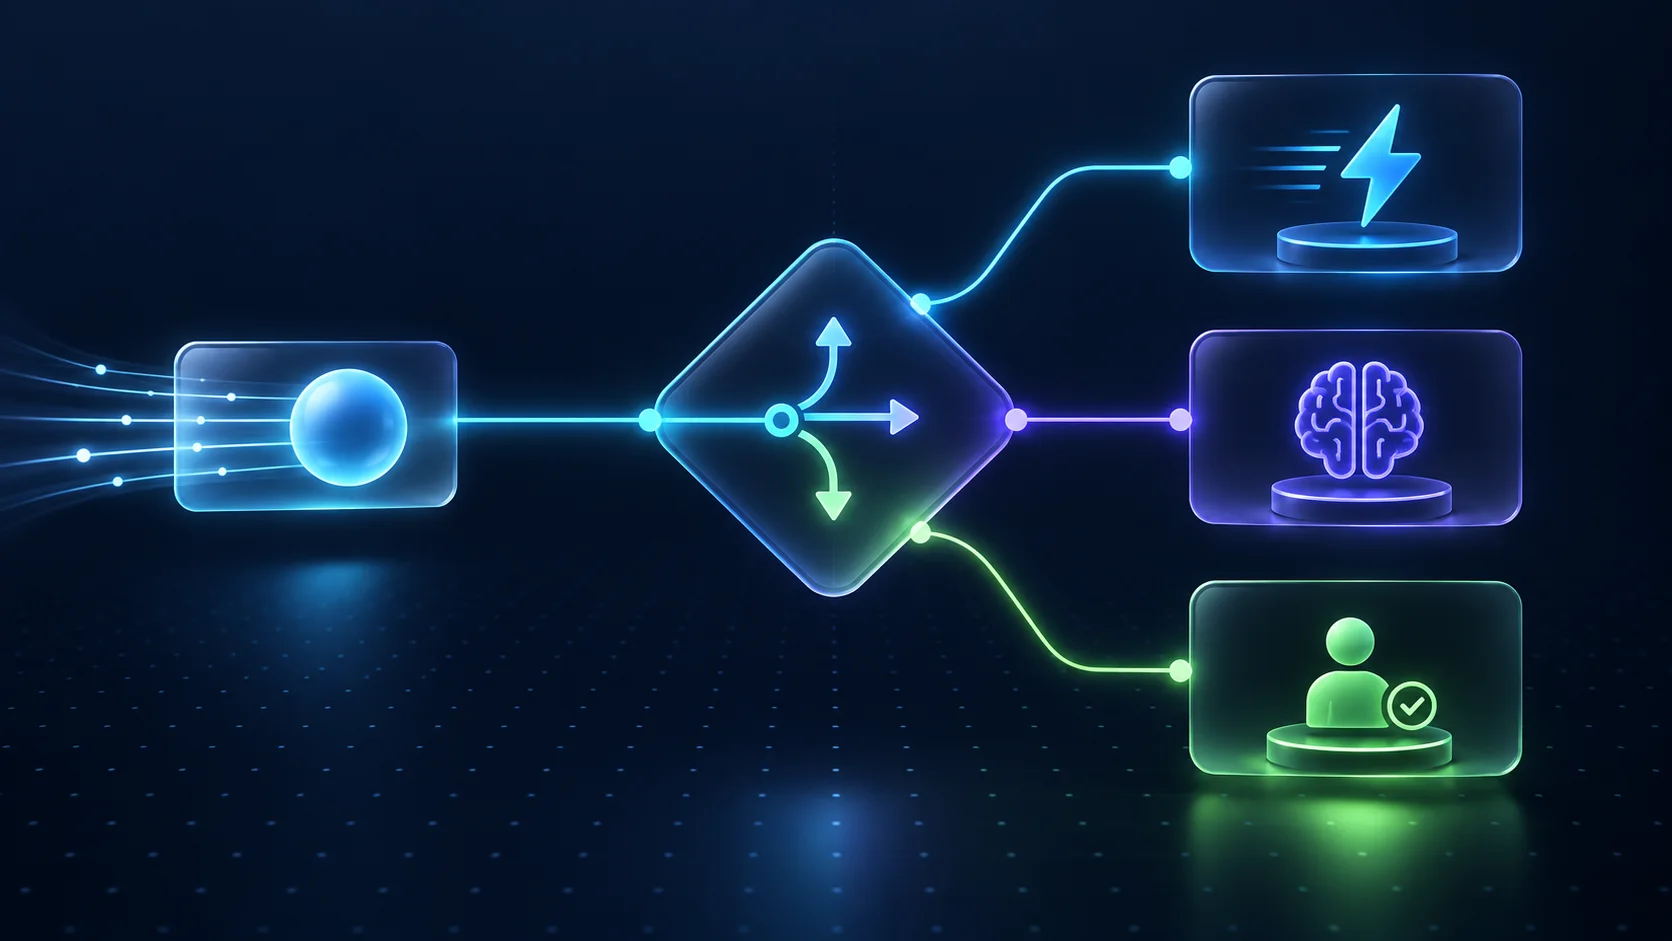
Image: Separating judgment from execution makes routing, guardrails, and review policies easier to test.
Generated text is not authorization
An LLM can generate the sentence “I will delete this file,” but that sentence should not have deletion authority. The real action must pass through application code, permissions, and tool-parameter validation.
Jev’s result should not be treated as authorization either. It can judge whether the user explicitly requested deletion or whether a request looks high risk, but deterministic rules and permission systems should still decide whether execution is allowed.
Agents contain many small decisions
A single agent turn may need to:
- classify task type and difficulty;
- choose a fast model or a deeper model;
- decide whether an external tool is needed;
- validate the tool name, arguments, and target resource;
- score risk and decide whether confirmation is required;
- continue, retry, degrade, or pause;
- record the result and update context.
Not all of these need long-form reasoning. Breaking them into atomic questions is often easier to maintain than continuously expanding a system prompt.
Where Jev AI fits
A clear layered architecture can look like this:
user request
     ↓
state builder  ──► permissions and hard rules
     ↓
Jev decision layer
     ├─ route model
     ├─ score risk
     ├─ check intent
     └─ request human review
     ↓
orchestrator
     ├─ call LLM
     ├─ call tool
     └─ ask user
     ↓
validator + audit log
Jev does not need to know the entire internal implementation of the agent. It needs only the State and questions required for the current judgment. Models, tools, and business policies can evolve independently.
If State, Choice, Score, and Noul are new to you, start with the Jev AI API tutorial. For the division of labor between Jev and generative LLMs, read Jev AI vs LLMs.
Pattern 1: route the model before calling
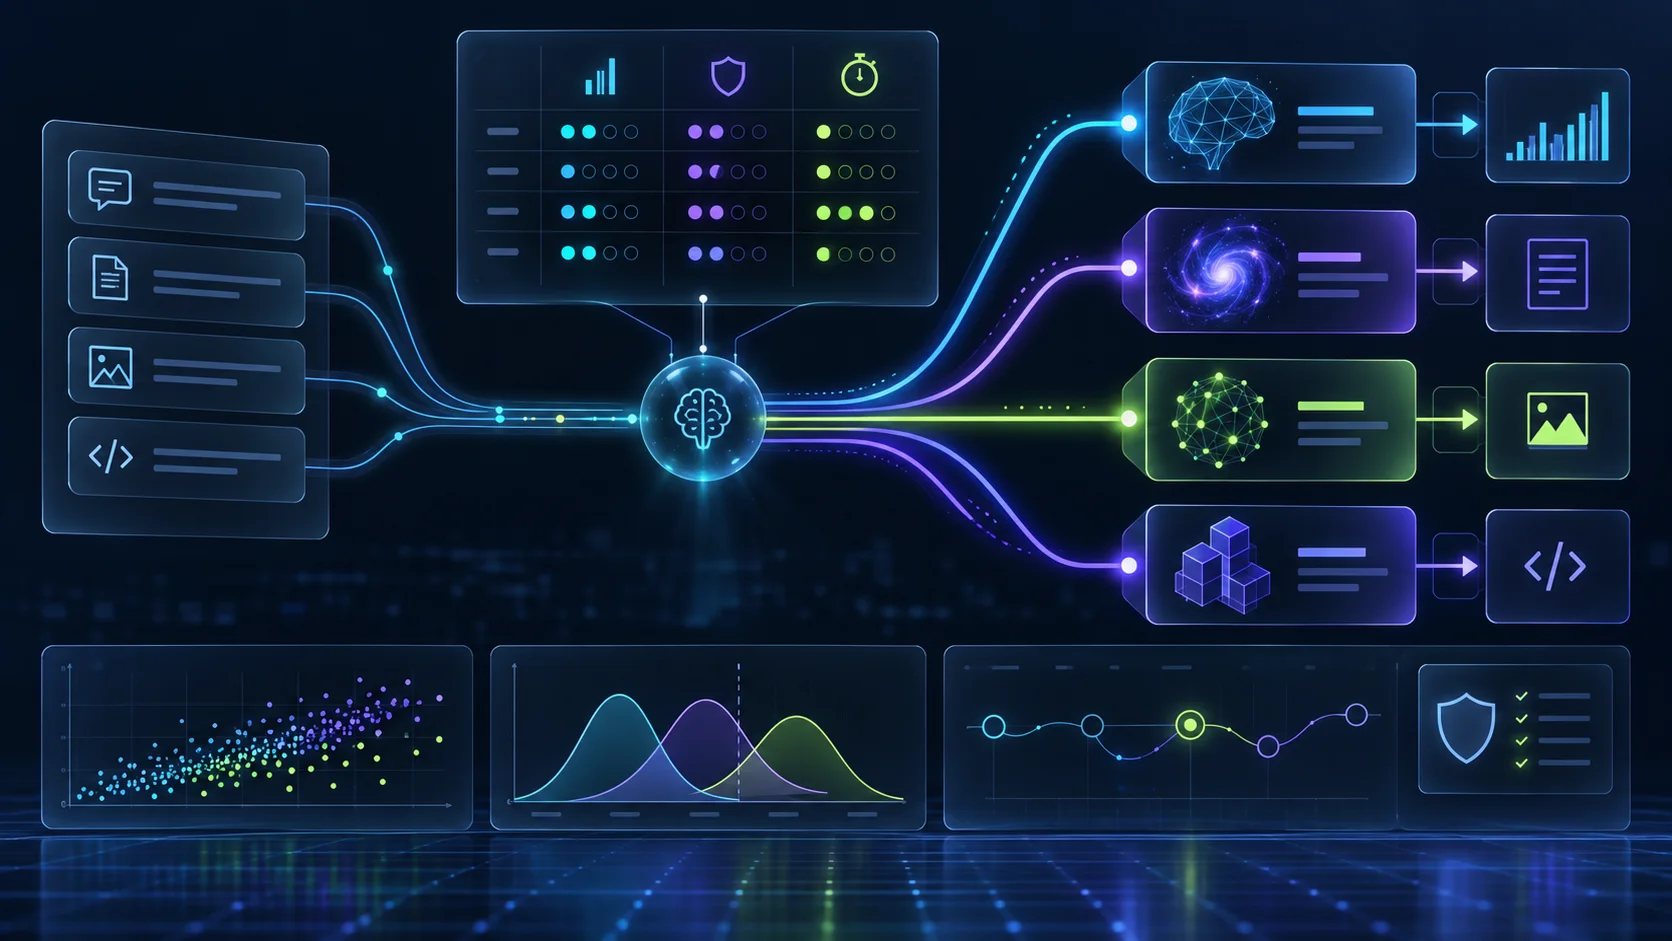
An agent should not send every request to the most expensive and slowest model. Use Jev to make small judgments such as:
- Does the task require complex reasoning?
- Does it require a tool call?
- Does it involve sensitive data or a high-impact action?
- Can a short answer satisfy the request?
A practical routing strategy
decision = jev.system_one(
    state={
        "request": user_message,
        "conversation_summary": summary,
        "available_tools": tool_catalog,
    },
    questions={
        "difficulty": Score(rubric=["simple", "moderate", "complex"]),
        "needs_tool": Noul("Does this request require a tool call?"),
        "sensitive": Noul("Does this request involve sensitive data or action?"),
    },
)
The orchestrator can route simple work to a fast model, complex work to a stronger model, and sensitive work to a guardrail flow. Jev suggests a path; it does not grant final permission.
Routing mistakes to avoid
- Do not let one score decide every model choice.
- Do not treat a probability threshold as a security proof.
- Do not include an untested full tool catalog in every State.
- Do not skip authorization because one judgment has high confidence.
Pattern 2: guard tool calls
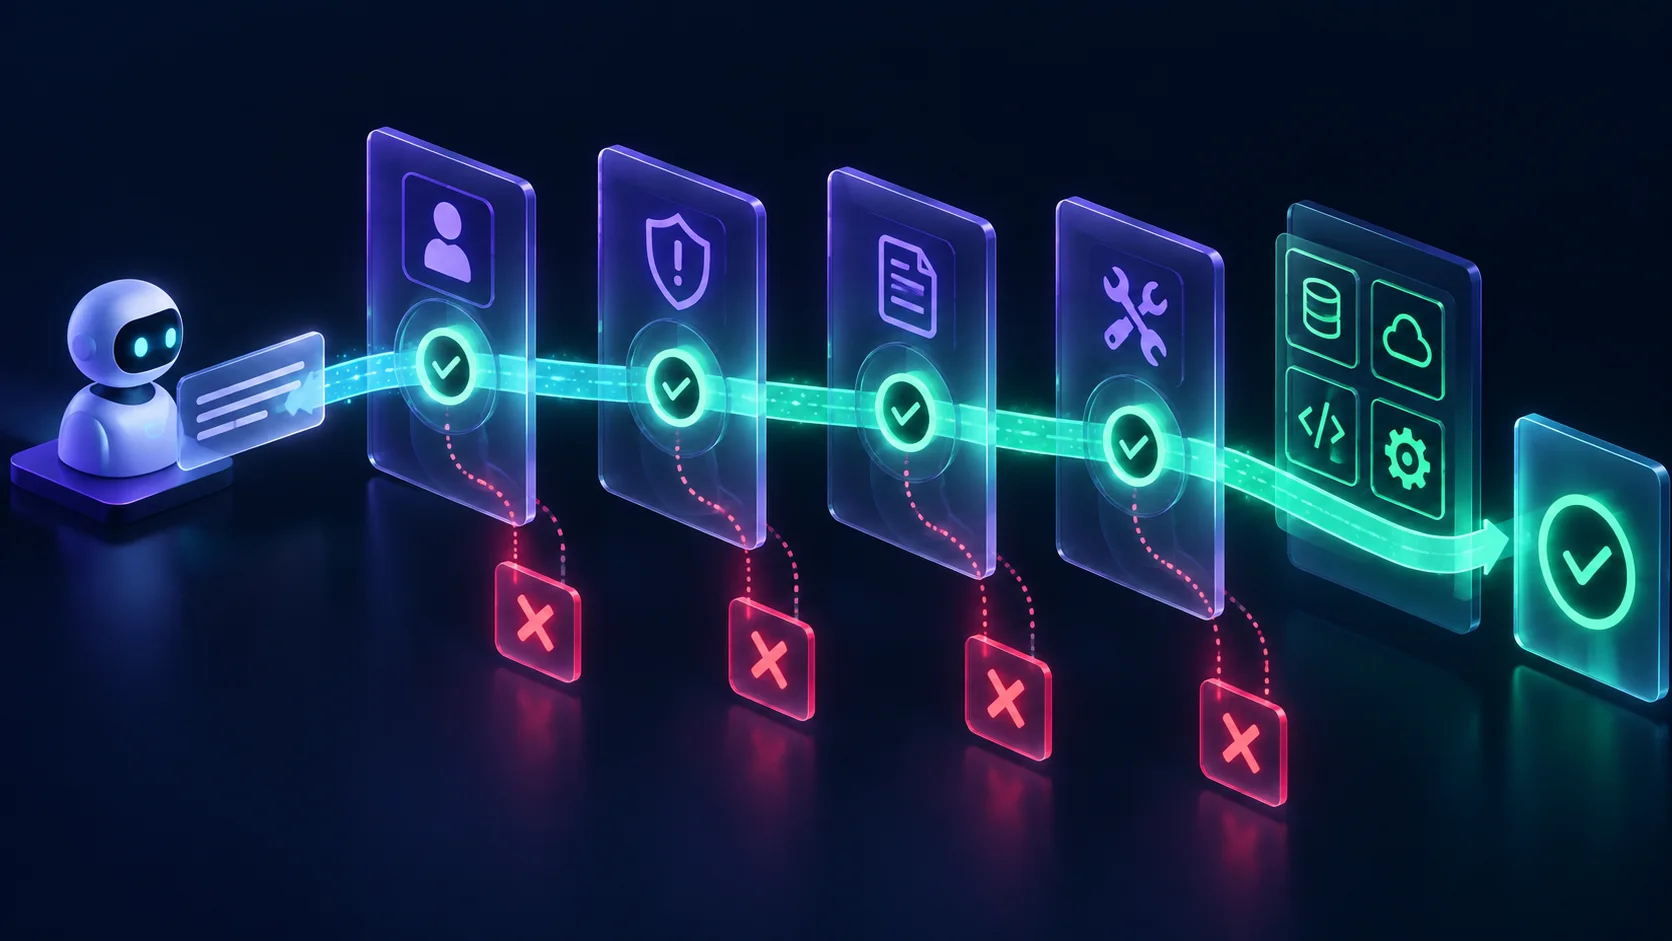
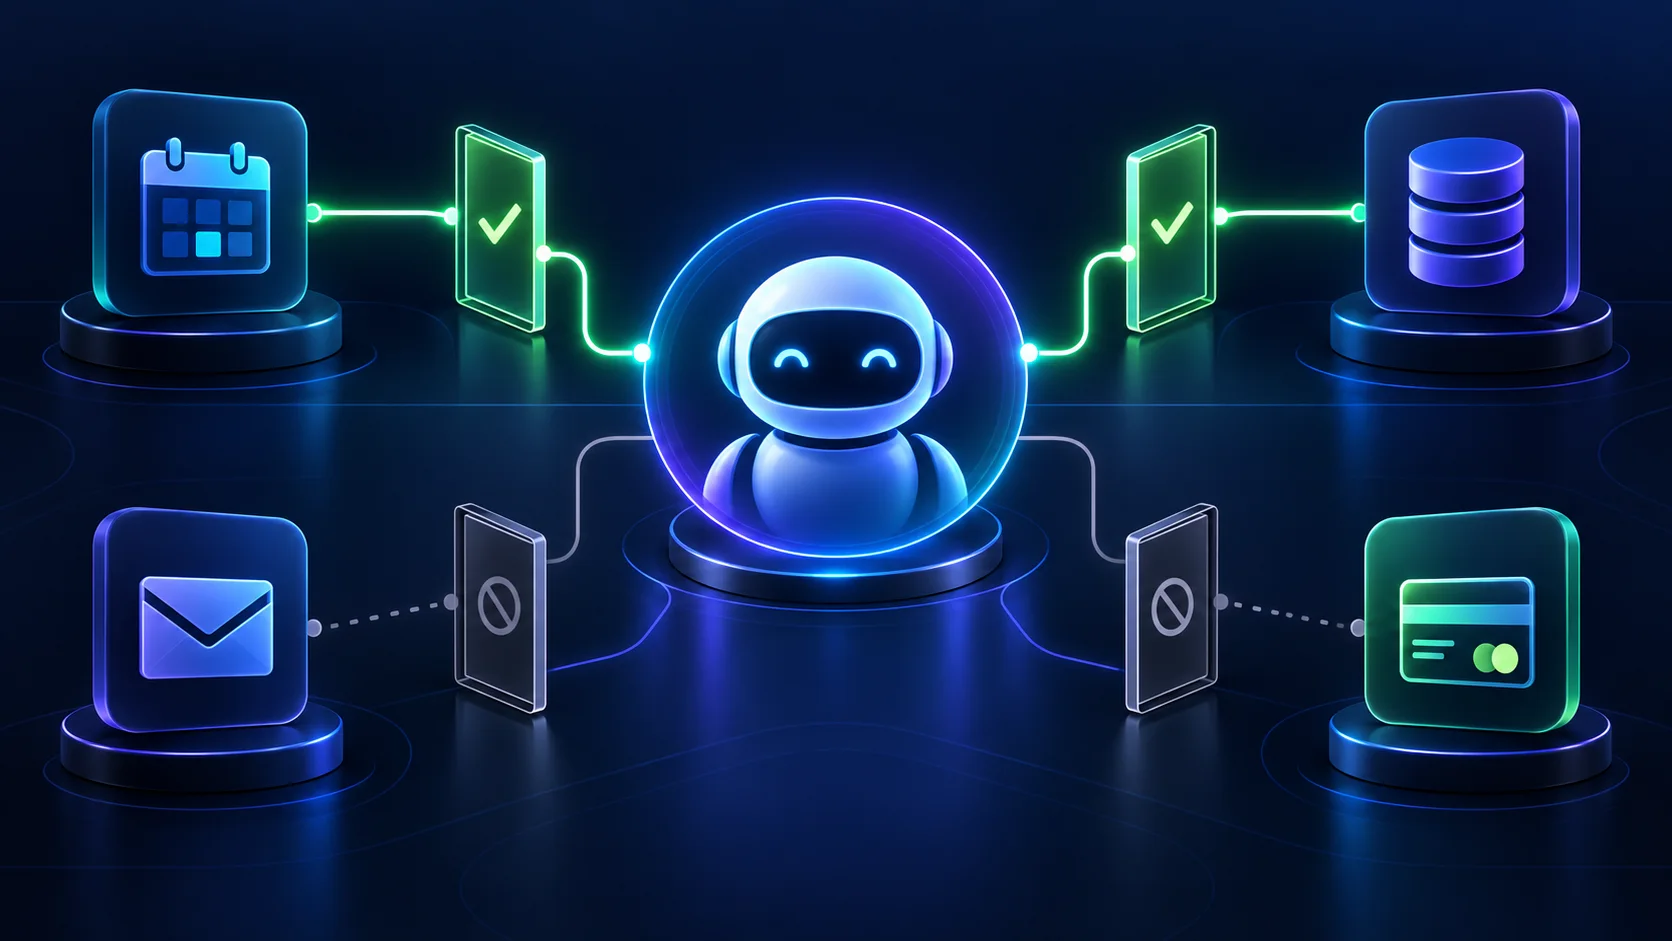
Image: Tool calls should pass intent checks, parameter validation, permissions, and risk paths before execution.
For an agent, the most important guardrail is often not “reject all dangerous content.” It is ensuring that a side-effecting action has enough context, valid parameters, and explicit confirmation.
Four layers of defense
Layer 1: hard rules
Check the user, role, resource ownership, amount limits, allowlisted tools, and parameter types first. If a hard rule fails, do not call Jev or an LLM; reject the action or route it to a person.
Layer 2: intent judgment
Use Noul to judge whether the user explicitly requested the action. “Did the user explicitly ask to delete this project?” is different from “Did the user ask how deletion works?”
Layer 3: risk scoring
Use Score for blast radius, reversibility, sensitivity, and external visibility. Payments, permission changes, bulk deletion, and external messaging should have higher review thresholds.
Layer 4: confirmation and audit
High-risk actions should show the target, parameters, and consequences to the user, request explicit confirmation, and record the decision, version, actor, and tool result. Revalidate parameters after confirmation; do not treat an old confirmation as permanent authorization.
Pattern 3: use probability to trigger review
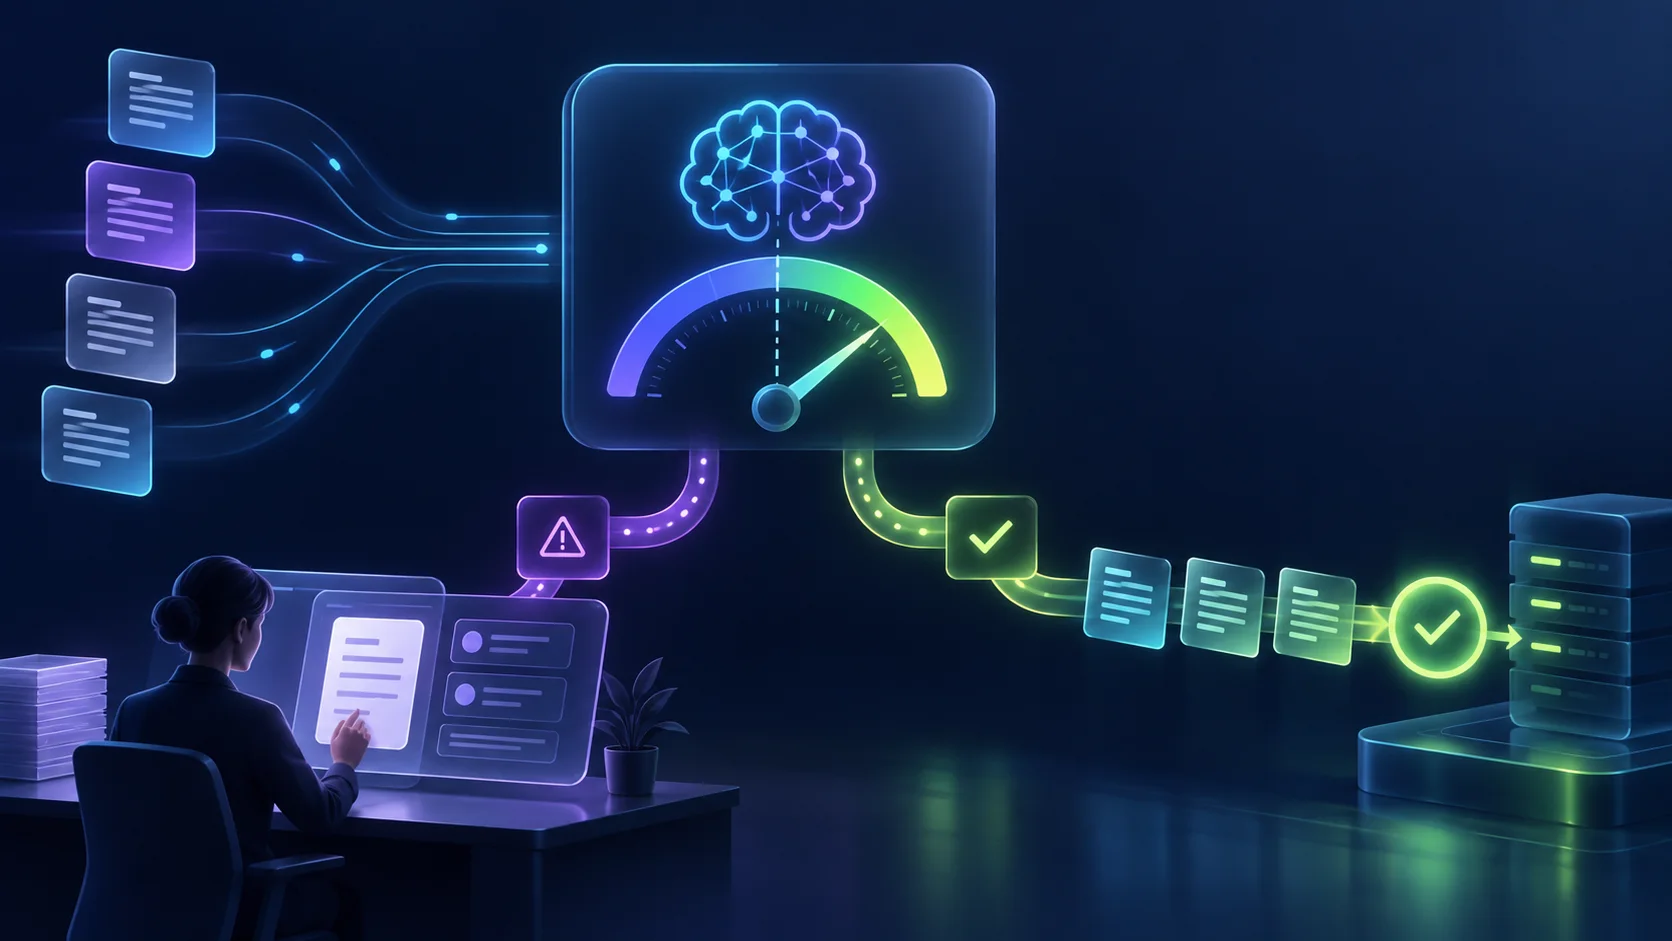
Jev’s probability and confidence are most useful for choosing the level of automation, not replacing human judgment. A system can create three paths:
| Result state | Handling |
|---|---|
| High confidence, low risk | Continue automatically and log the result |
| Near a threshold or missing context | Ask for more information or sample for review |
| High risk or low confidence | Pause the agent and route to a person |
Set thresholds by action, not by model globally. Automatic ticket classification may tolerate a lower threshold; refunds, deletion, permission changes, and external messages need higher thresholds and explicit confirmation.
What should a reviewer see?
A useful review interface should show:
- the original State or a redacted summary;
- the action the agent wants to take and the tool parameters;
- Jev’s questions, options, probabilities, and confidence;
- hard-rule and authorization results;
- controls to approve, reject, edit, or request more information.
Do not show only “AI recommendation: approve.” Reviewers need the facts and boundaries behind the judgment.
Designing agent State and questions
Put only decision-relevant facts in State
An agent’s long conversation may contain a lot of history, but each Jev question rarely needs all of it. Extract a task summary, current tool, resource details, user permissions, and the latest result in code before building a minimal State.
A small State reduces cost, limits sensitive-data exposure, and makes the judgment easier to reproduce.
One question, one judgment
Do not write a super-question such as:
“Is this safe, does it need confirmation, which model should we use, and are the parameters valid?”
Split it into questions such as:
intent_explicit: Did the user explicitly request the action?parameter_valid: Do the arguments satisfy the tool contract?risk_level: What is the risk level of the action?needs_human: Is human review required now?
Code can handle each result independently, and each question can have its own counterexamples.
Version the decision
Record the question definitions, option descriptions, rubric, model version, and threshold version. Without those fields, the team cannot explain why a past action was allowed or blocked after policies change.
Security and evaluation checklist
Before production, verify that:
- The agent cannot bypass hard rules to call a high-impact tool.
- Every side-effecting tool has an allowlist, parameter validation, and authorization check.
- Jev probabilities are signals; critical actions still have deterministic or human fallback.
- Review paths do not drop tasks because of a timeout or service outage.
- Every action is linked to input, questions, model, thresholds, and actor.
- Tests include normal, ambiguous, unauthorized, prompt-injection, and misleading inputs.
- Chinese, English, specialist terms, and missing context are covered.
- Routing or guardrail questions can be changed without rewriting the whole agent.
- Fallbacks are explicit: pause, ask for confirmation, hand off, or use a static rule.
- Community examples in the Jev AI Showcase are treated as inspiration, not as security proof.
The current Jev input boundary is text, JSON objects, and arrays of text. Images, audio, and video are not direct inputs. Non-English and domain-specific data should be evaluated with your own samples rather than treated as covered by product positioning.
Frequently asked questions
Can Jev guarantee that an agent will not make mistakes?
No. Jev provides probability and confidence signals, not a business-accuracy or safety guarantee. Reliable agents still need permissions, hard rules, parameter validation, human review, and audit logs.
Why not let the LLM decide whether something is safe?
An LLM can help with understanding and explanation, but it should not be the only owner of final authorization. Separating small judgments makes thresholds, counterexamples, and failure paths independently testable.
Can high confidence skip human confirmation?
For low-risk actions, perhaps. For high-impact actions, confidence alone is not enough. Payments, deletion, permission changes, and external communication should combine model signals with rules, authorization, and explicit confirmation.
Is Jev right for every agent?
Not necessarily. If an agent mainly writes and converses, an LLM remains the center. If it needs frequent routing, tool selection, risk scoring, and escalation, Jev is a strong candidate for the decision layer.
How should I start?
Test one low-risk judgment in the Jev AI Playground, then follow the API tutorial for server-side integration. Once the basic flow works, add routing and guardrails to your orchestrator.
Conclusion: make agent actions explainable
Reliable agents do not need more permissions; they need better boundaries. Jev AI can make the hidden decisions around routing, tool use, escalation, and continuation explicit, while code and people keep control of the final action.
Start with one low-risk tool, log every judgment and final action, and refine questions and thresholds from real failures. That is how Jev AI becomes a stable decision layer instead of another prompt that is difficult to audit.
Research date: 2026-09-20
Primary sources: Jev AI homepage, Jev AI documentation, Jev AI Showcase, TypeSafe introduction